MACULA
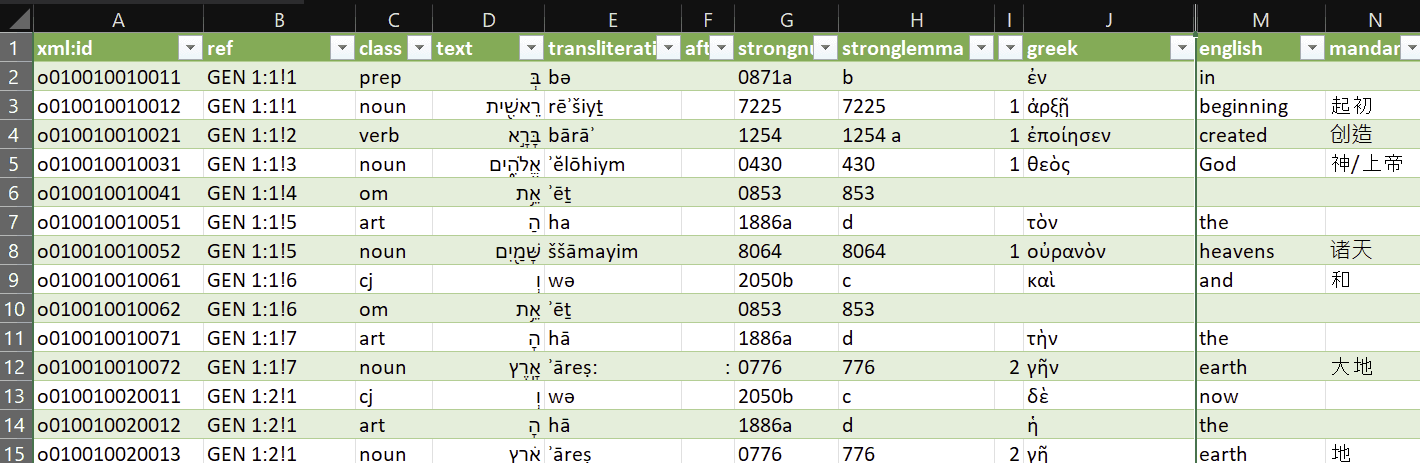
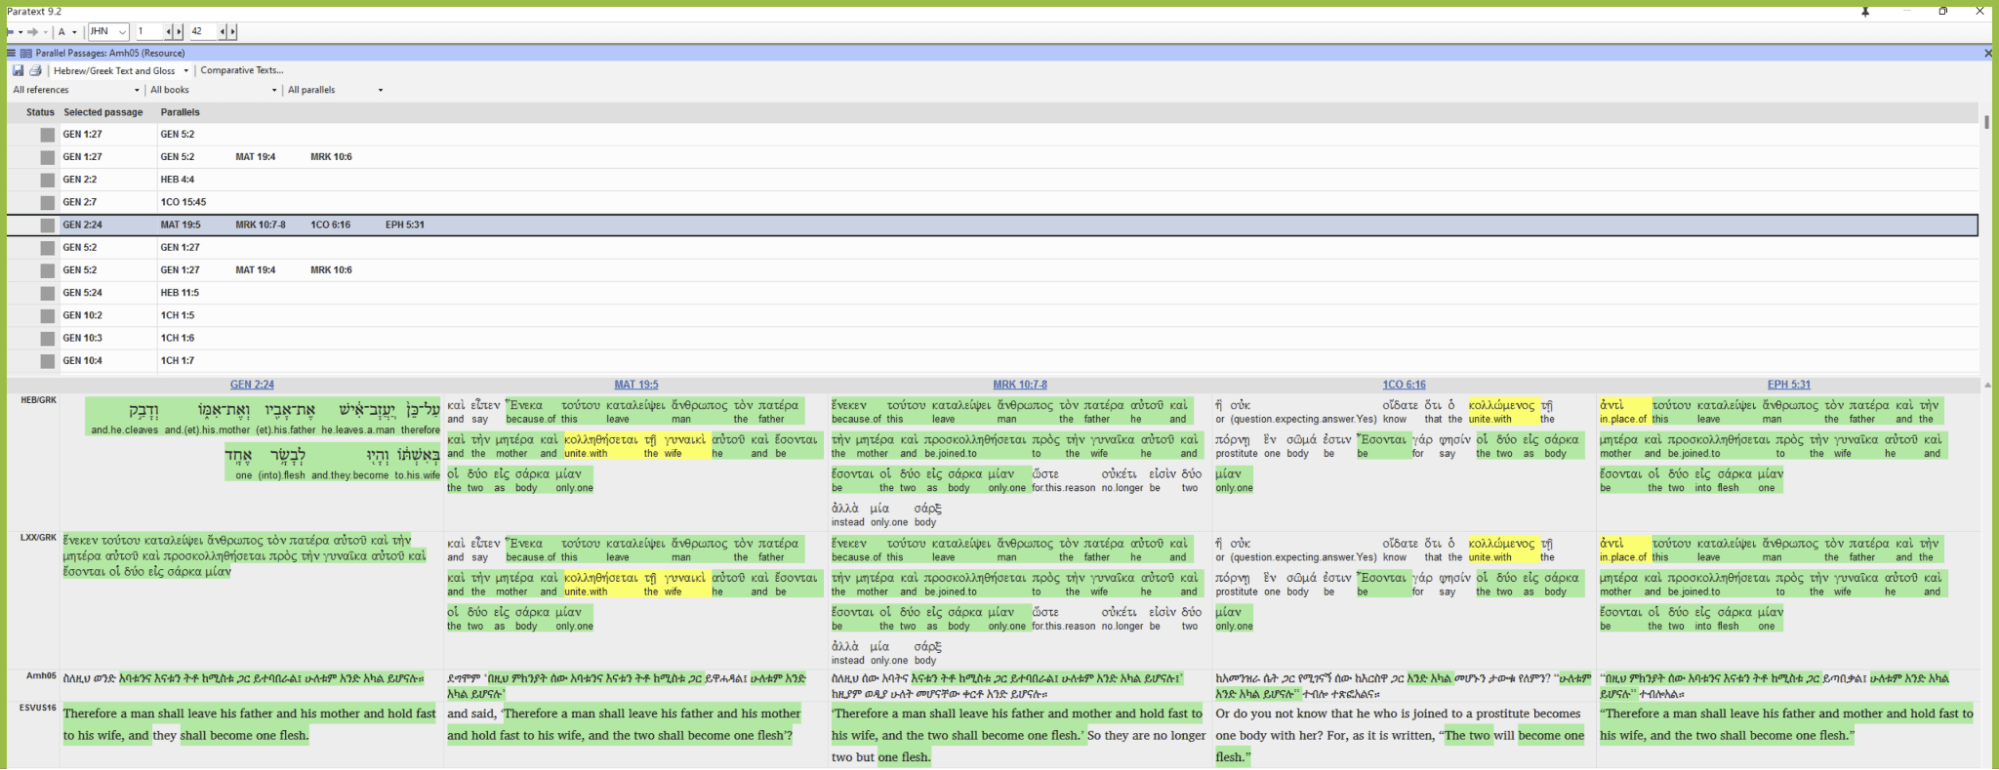
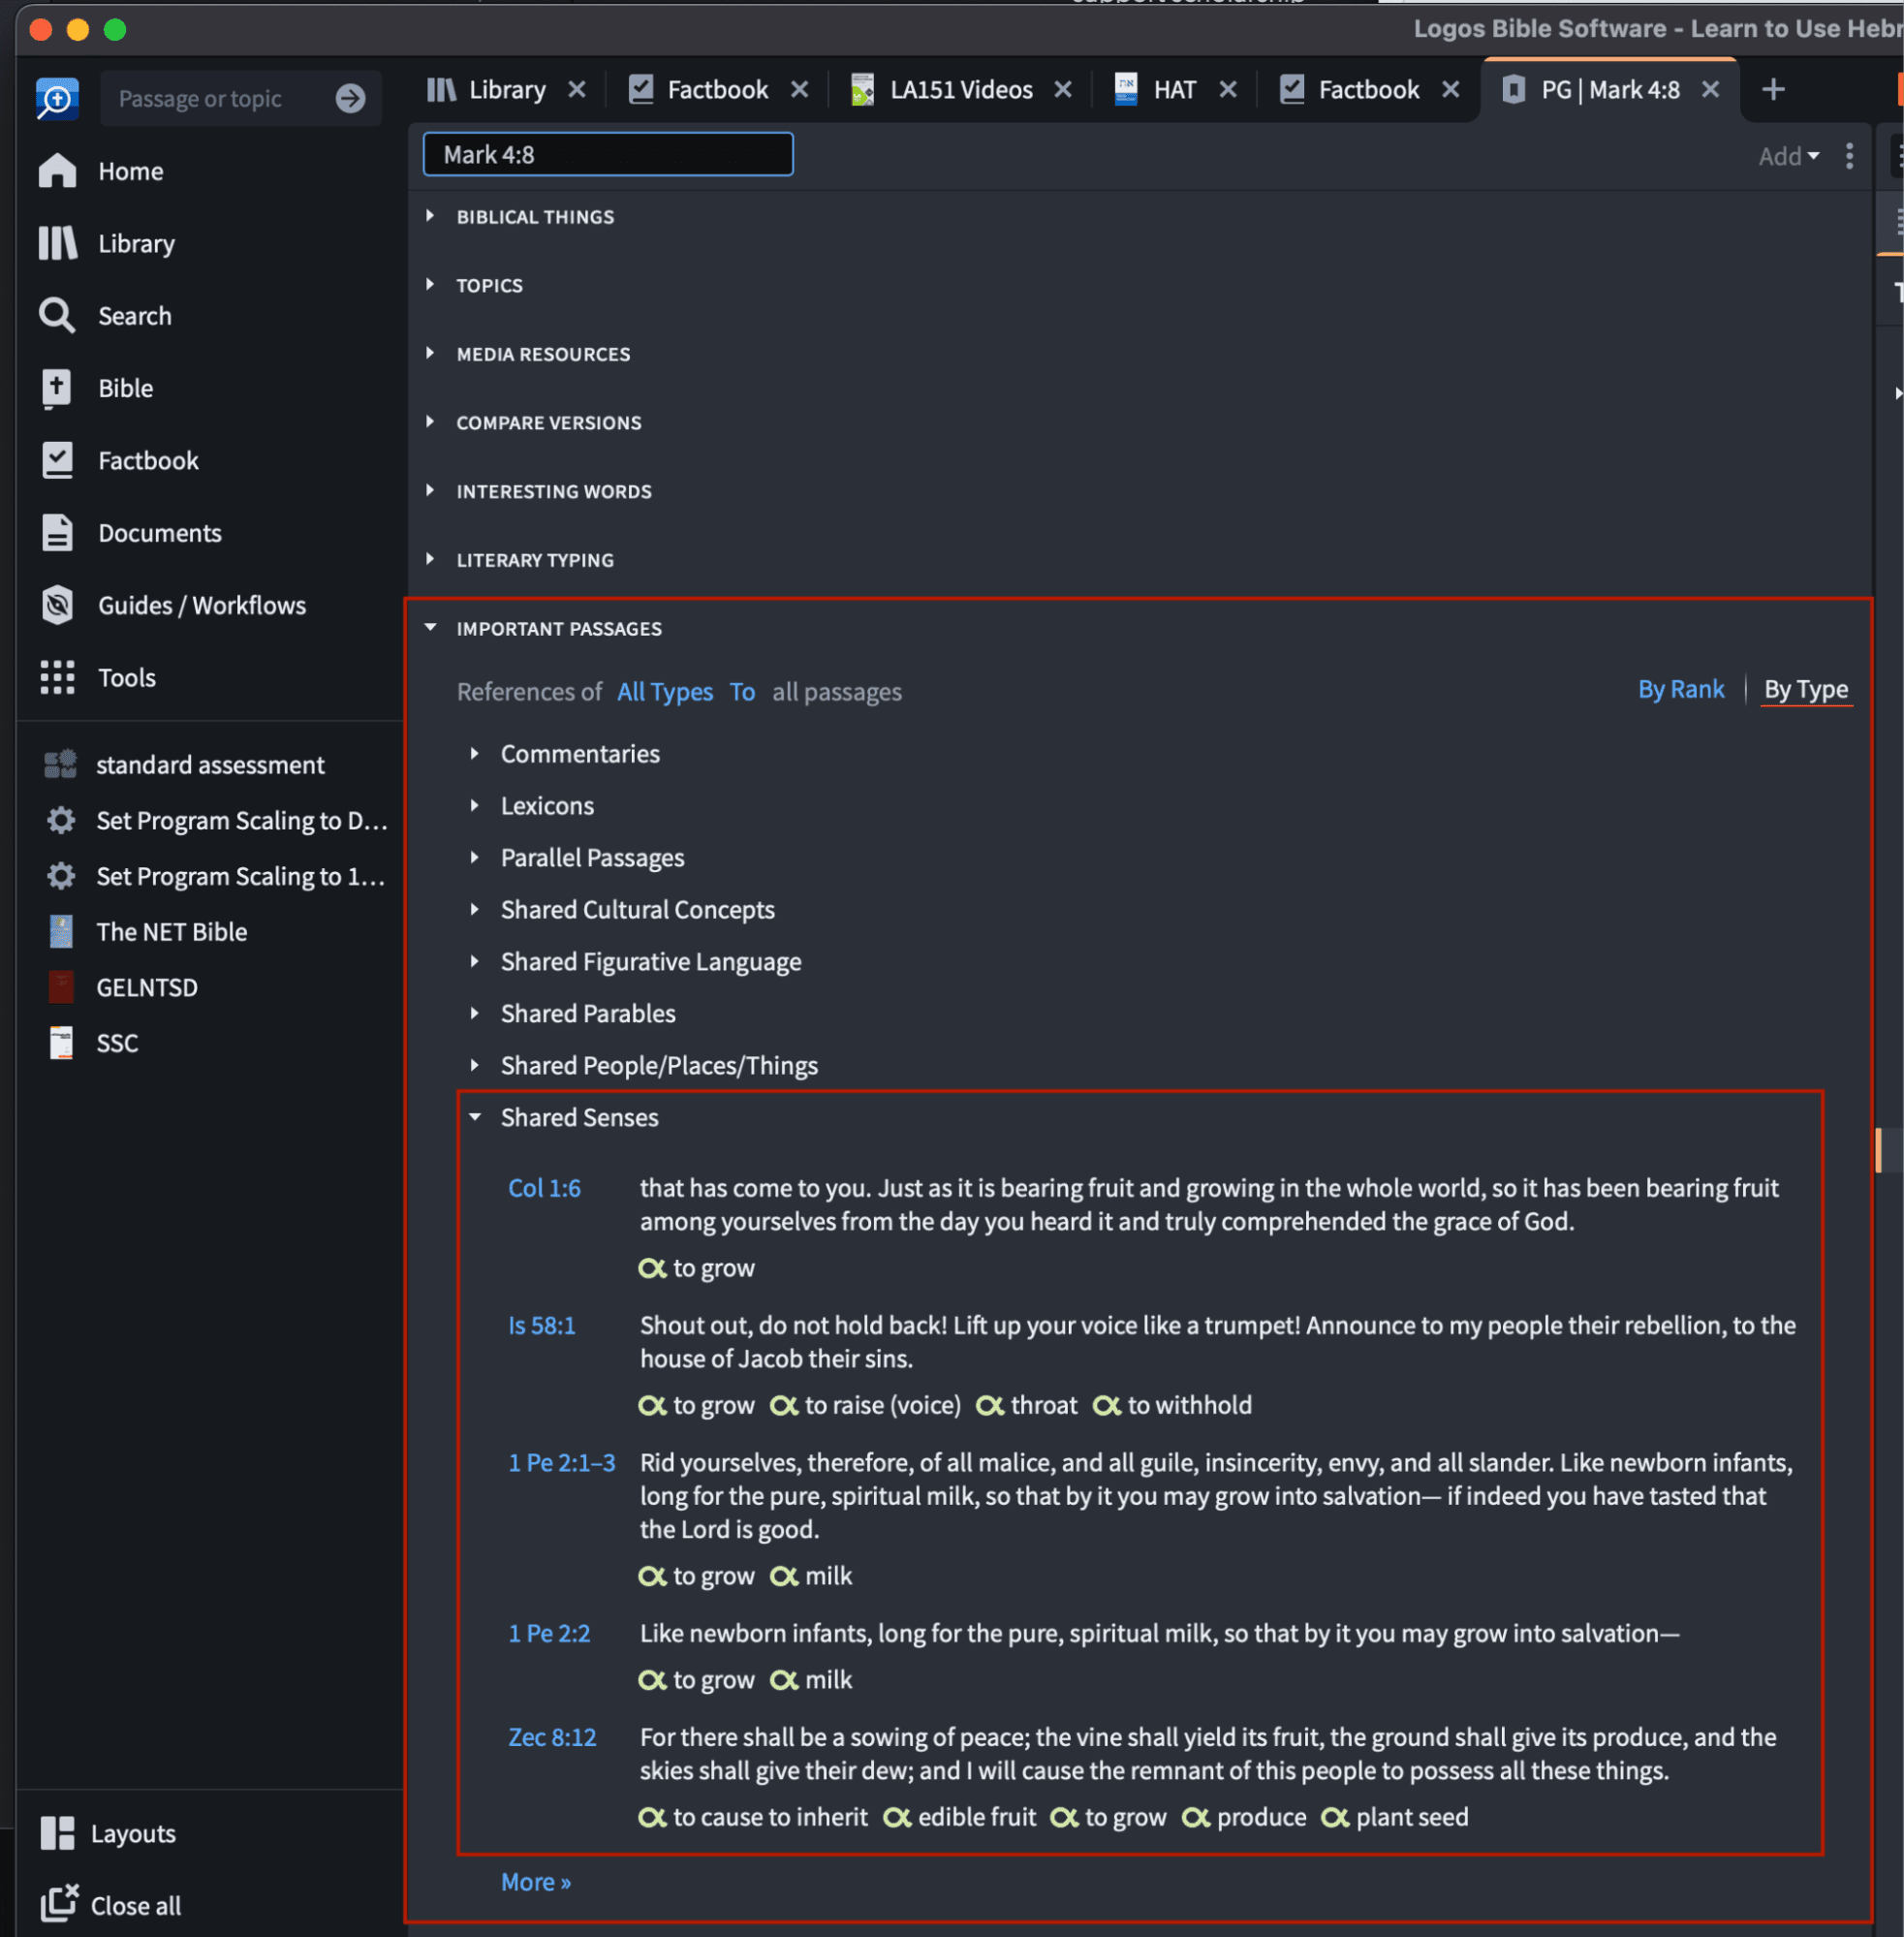
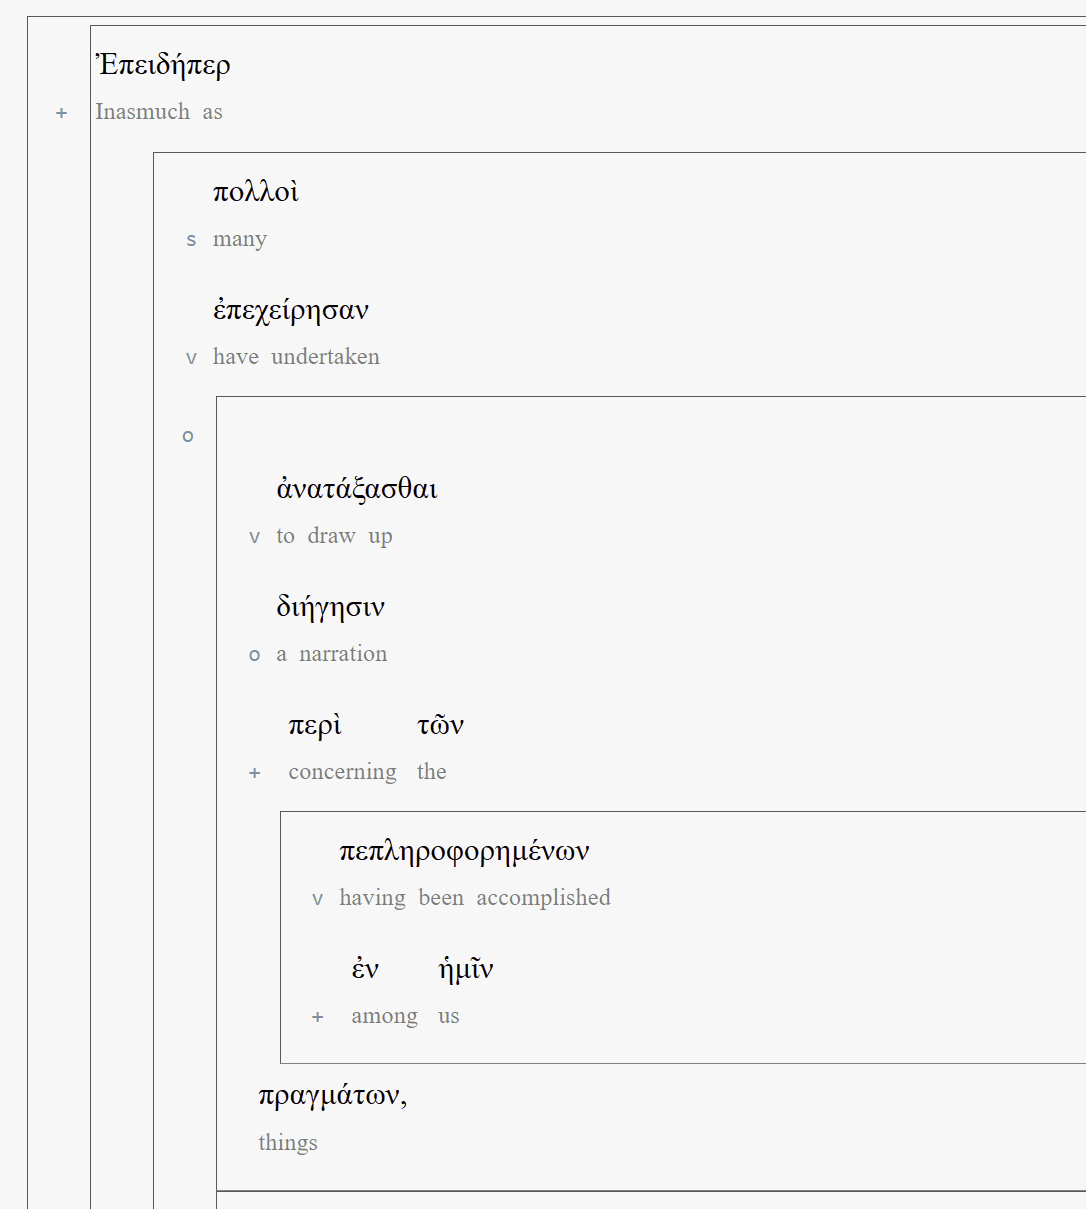
MACULA 包含丰富的 datasets (可通过 GitHub 和 API 访问)。这些 datasets 提供了希伯来圣经和希腊新约每一句的许多语言描述层,包括句法结构、形态、语义域、关系、所指、释义和引语等其他方面。
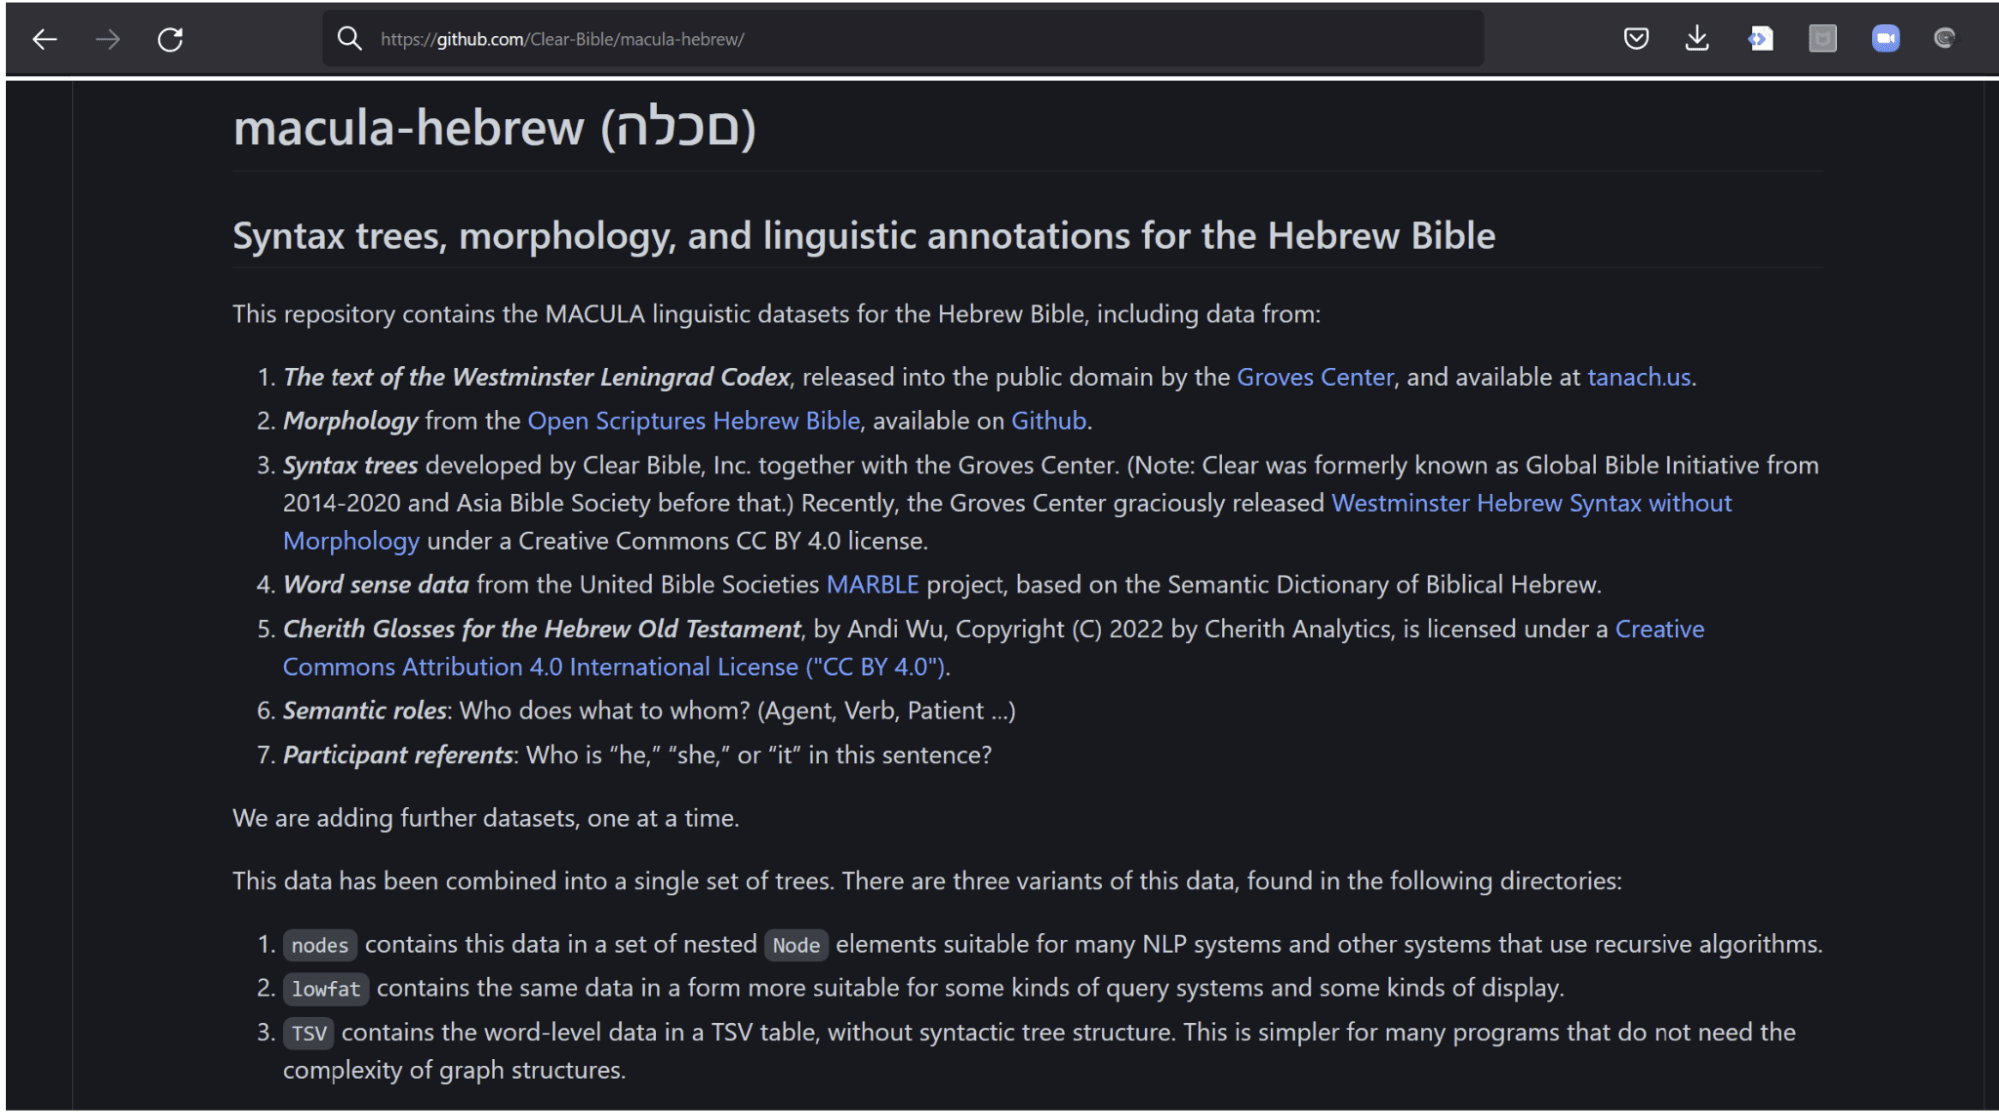
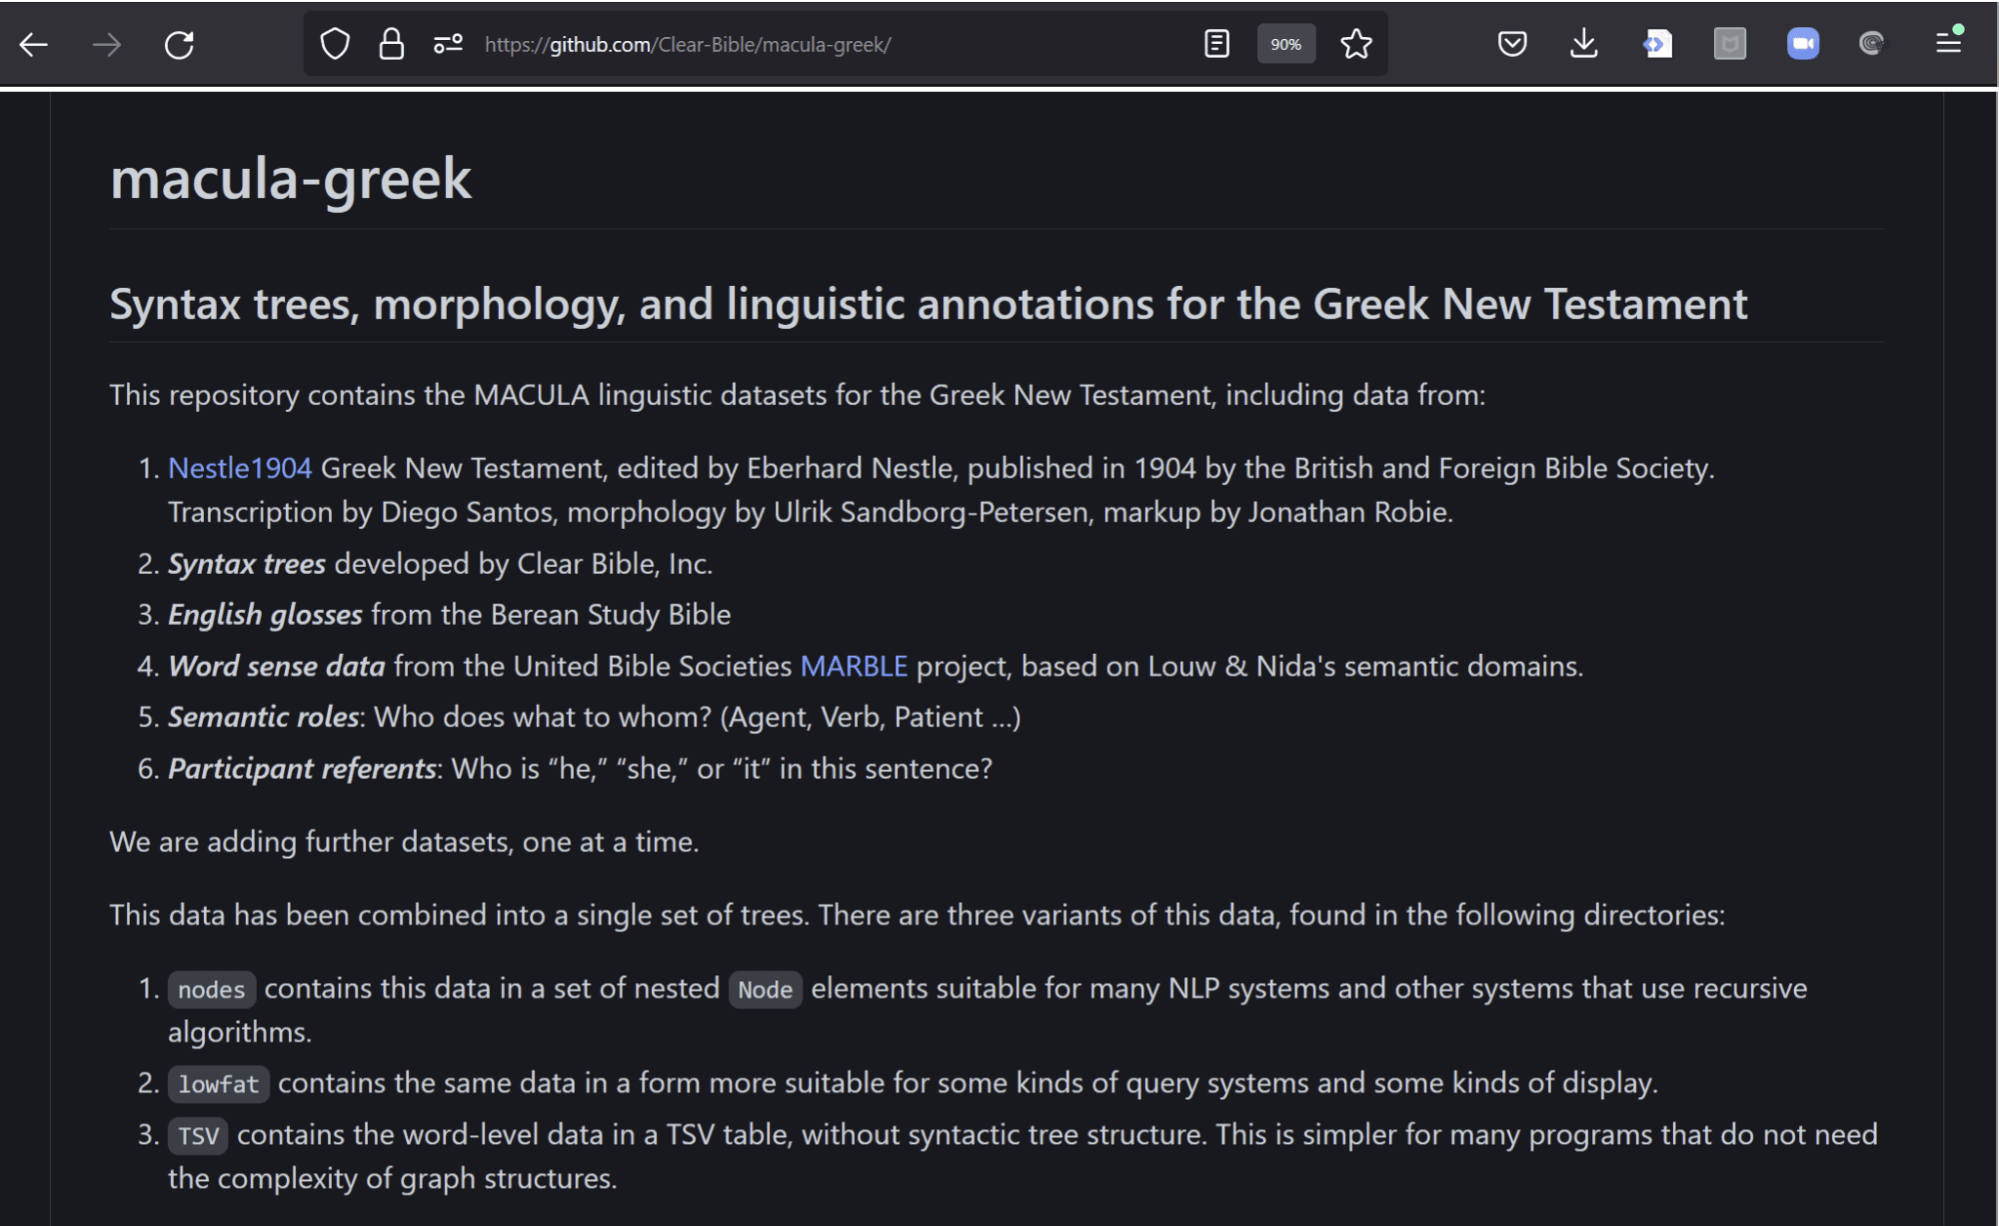
MACULA 可供具有丰富圣经语言和语言学知识的资源创作者或研究人员使用,也可供不了解希伯来语和希腊语的程序员和自然语言处理实践者使用。 MACULA 的 datasets 采用免费许可,并在 GitHub 上公开。
https://github.com/Clear-Bible/macula-hebrew
https://github.com/Clear-Bible/macula-greek
在此 datasets 基础上,Clear 正在为圣经语言学者和不了解希腊语或希伯来语的严肃圣经学生创建用户环境。
屏幕
感言
"As a Data Scientist wanting to process the biblical texts, I have found the MACULA dataset to be extremely useful. The data is very high quality, and it's very straightforward for me to import and use it in developing applications!"
Mark Woodward, Data Scientist, SIL International
"The MACULA data sets help translation consultants quickly recognize features, including participant reference and word sense, of the biblical texts. We appreciate the way it already integrates UBS and other data sets and look forward to even richer data in the future."
Milt Jones, VP Bible Translation at Seed Company
"MACULA data has been a game changer for our team as we try to estimate the qualities of Bible translation drafts. The semantic domain information and glosses help us find missing, added, or modified information during review."
Daniel Whitenack, Data Scientist, SIL Internationa