MACULA
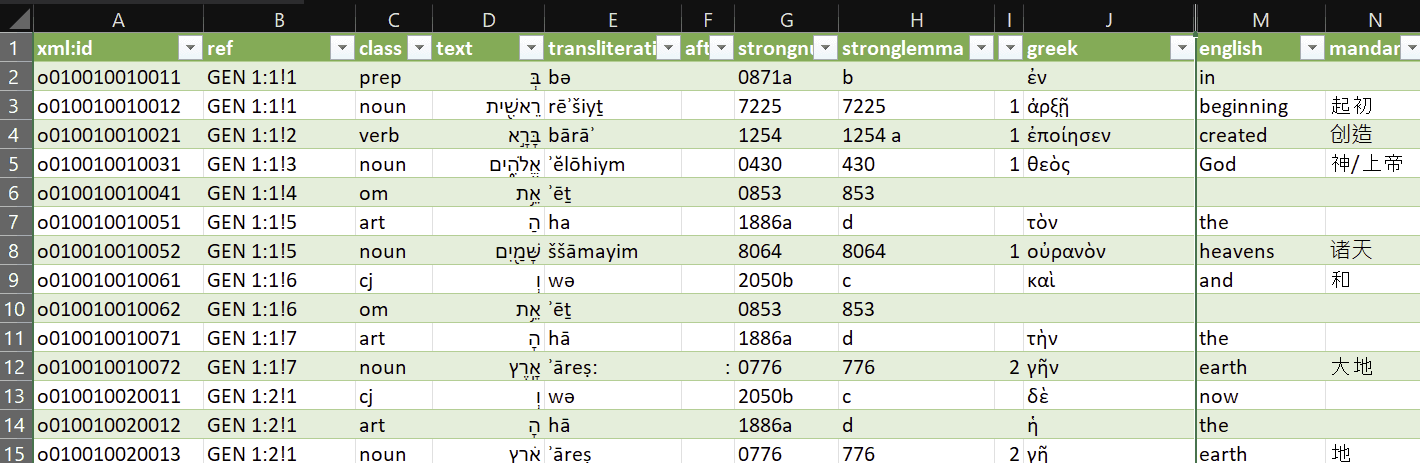
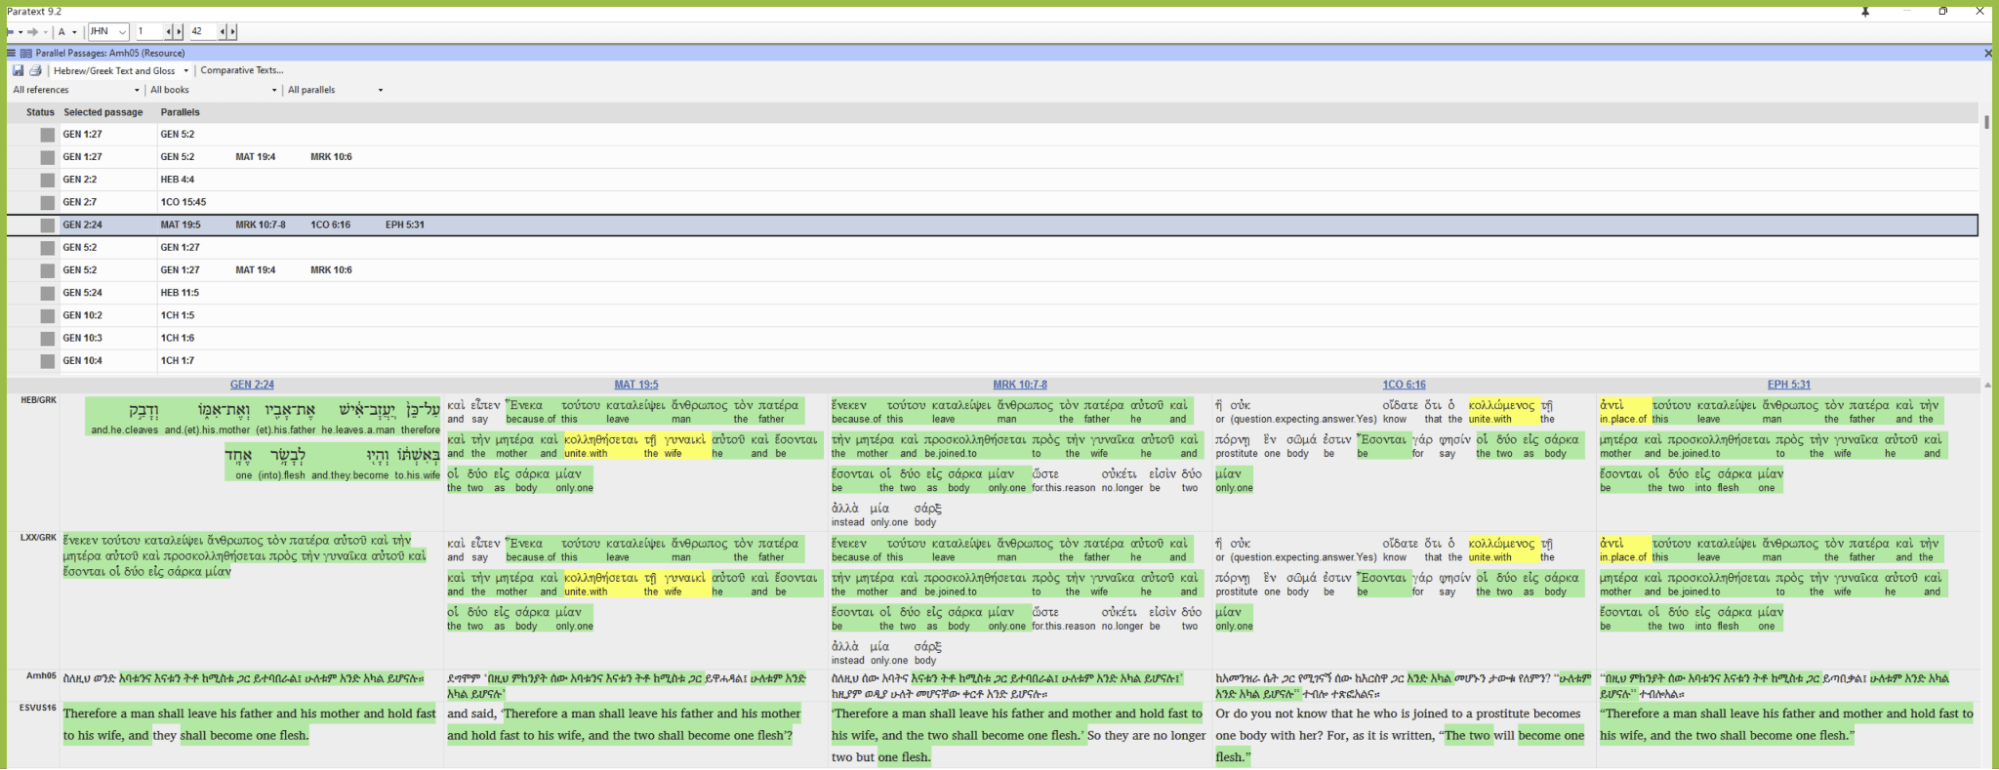
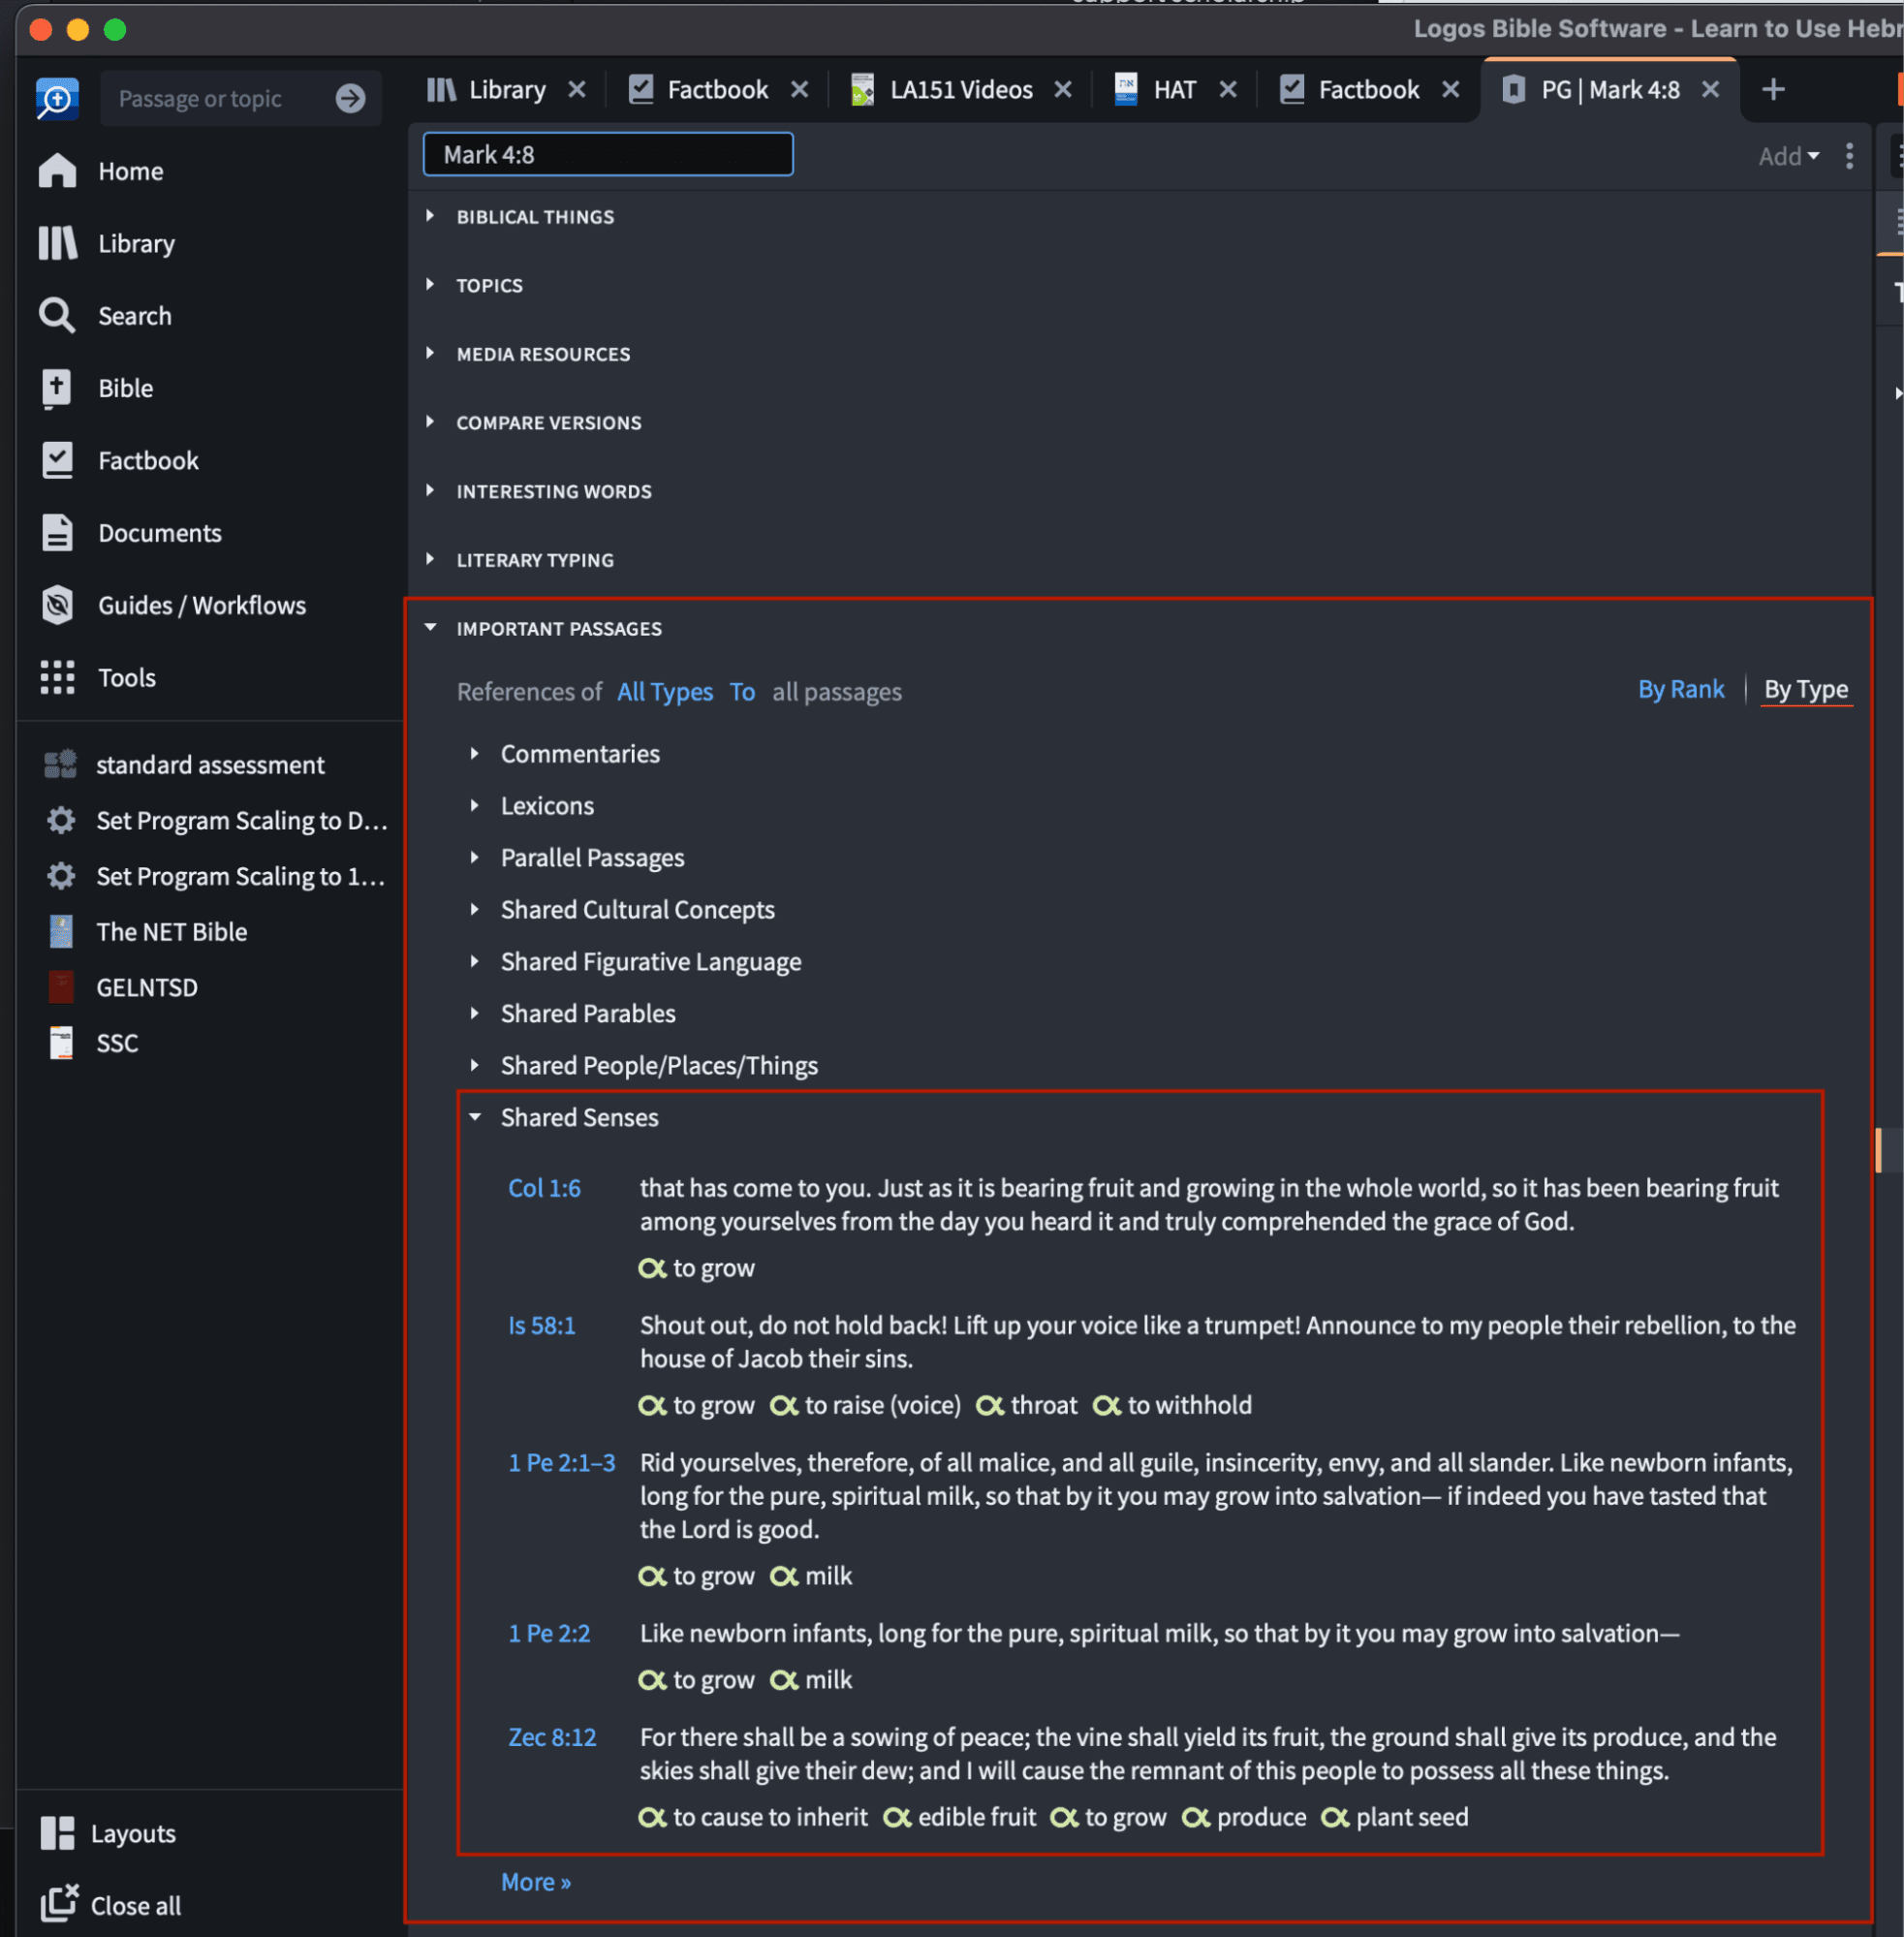
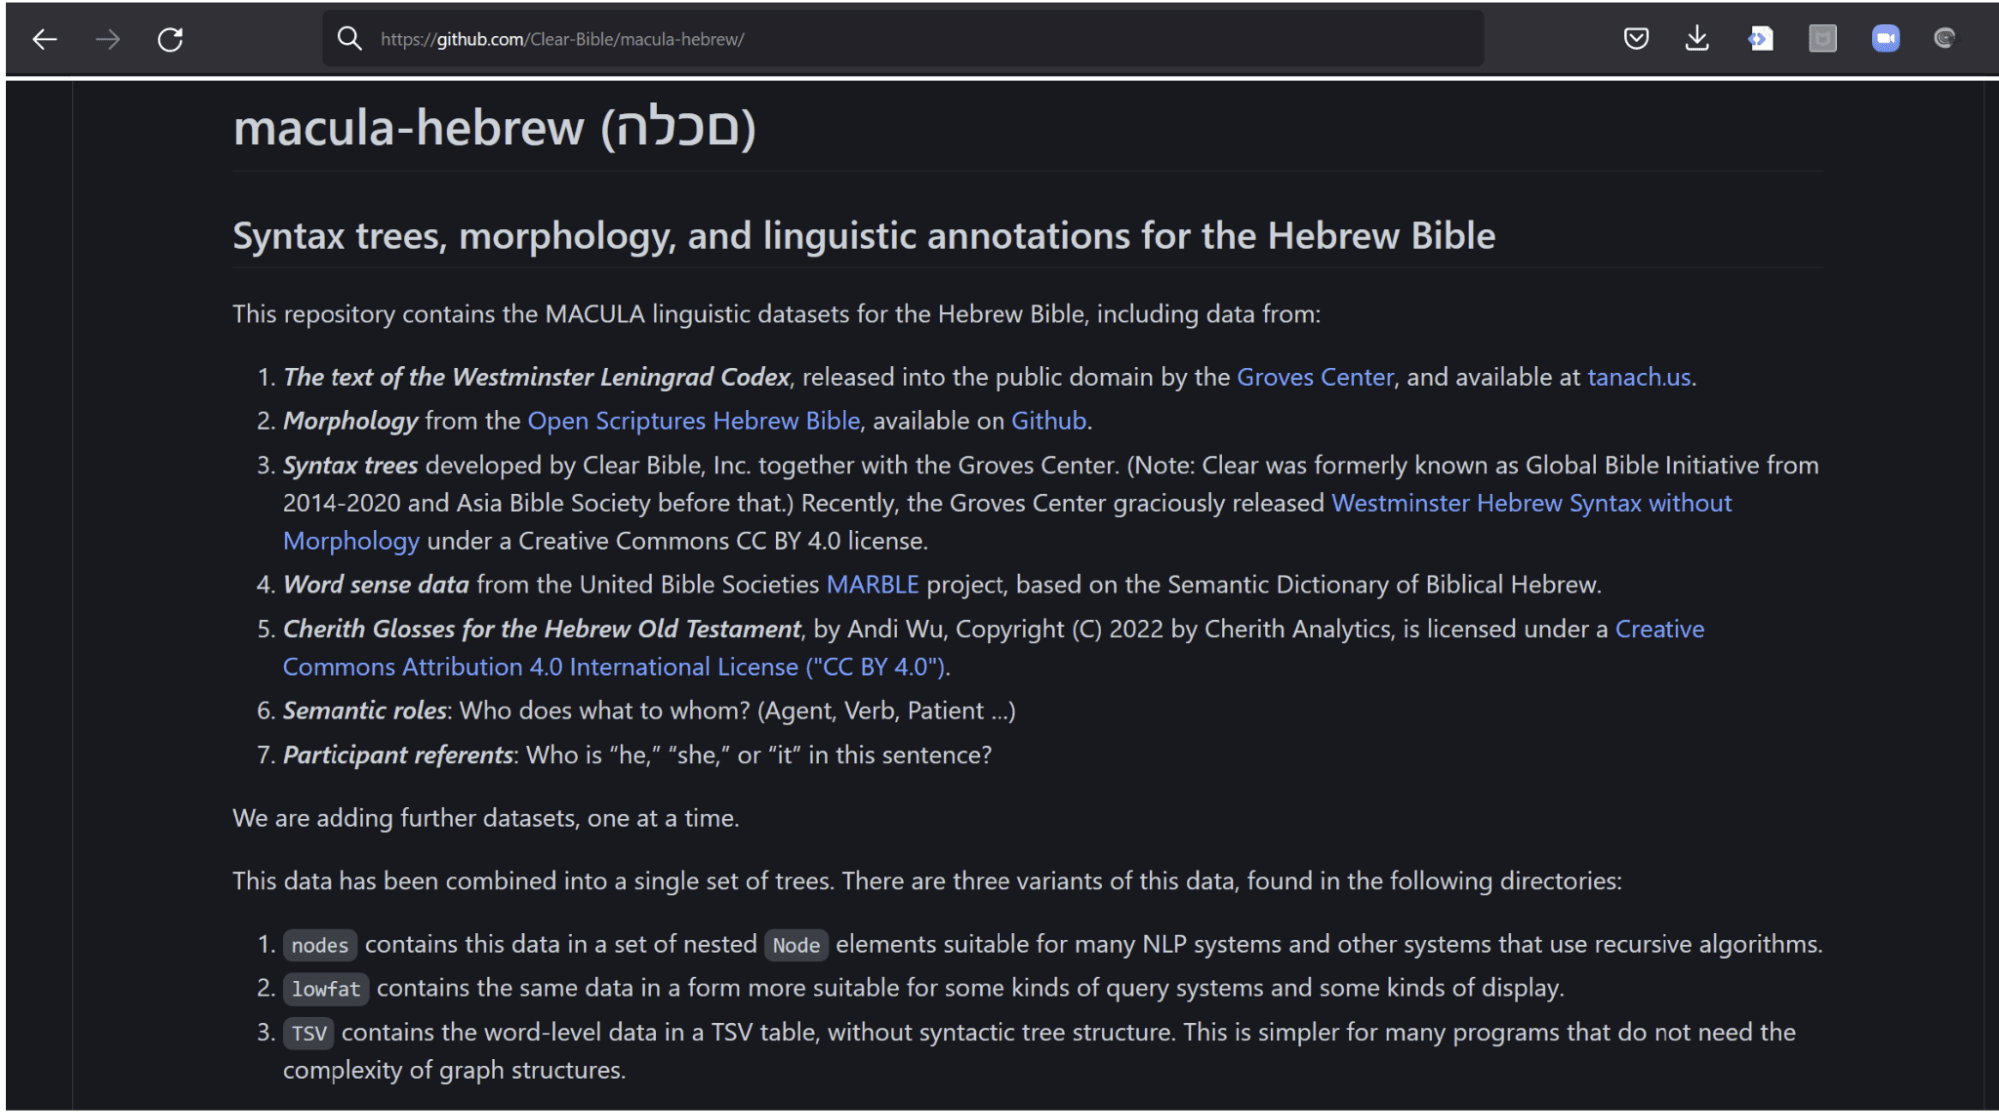
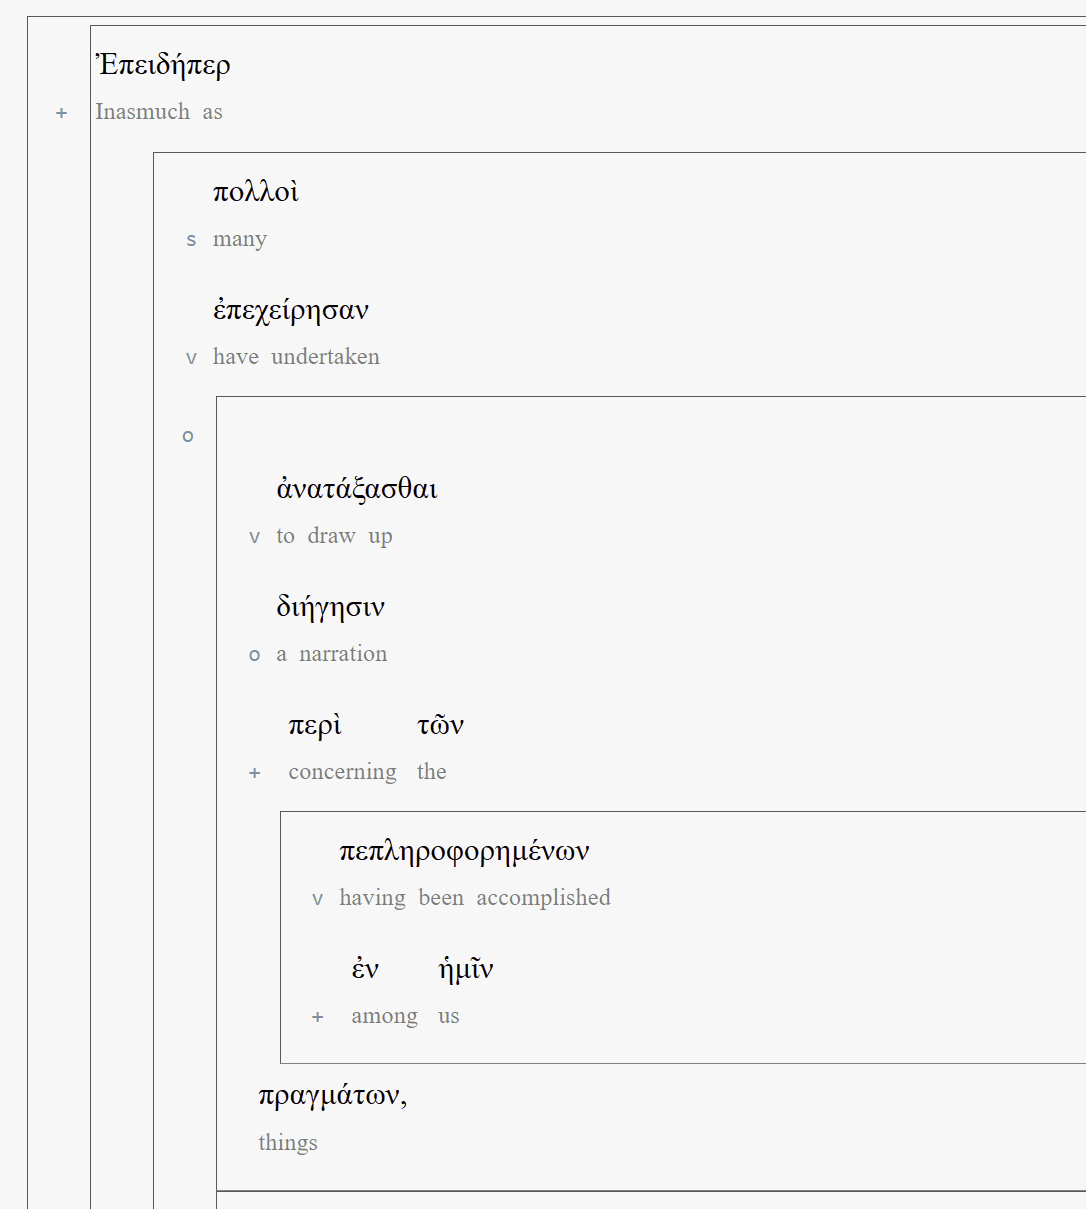
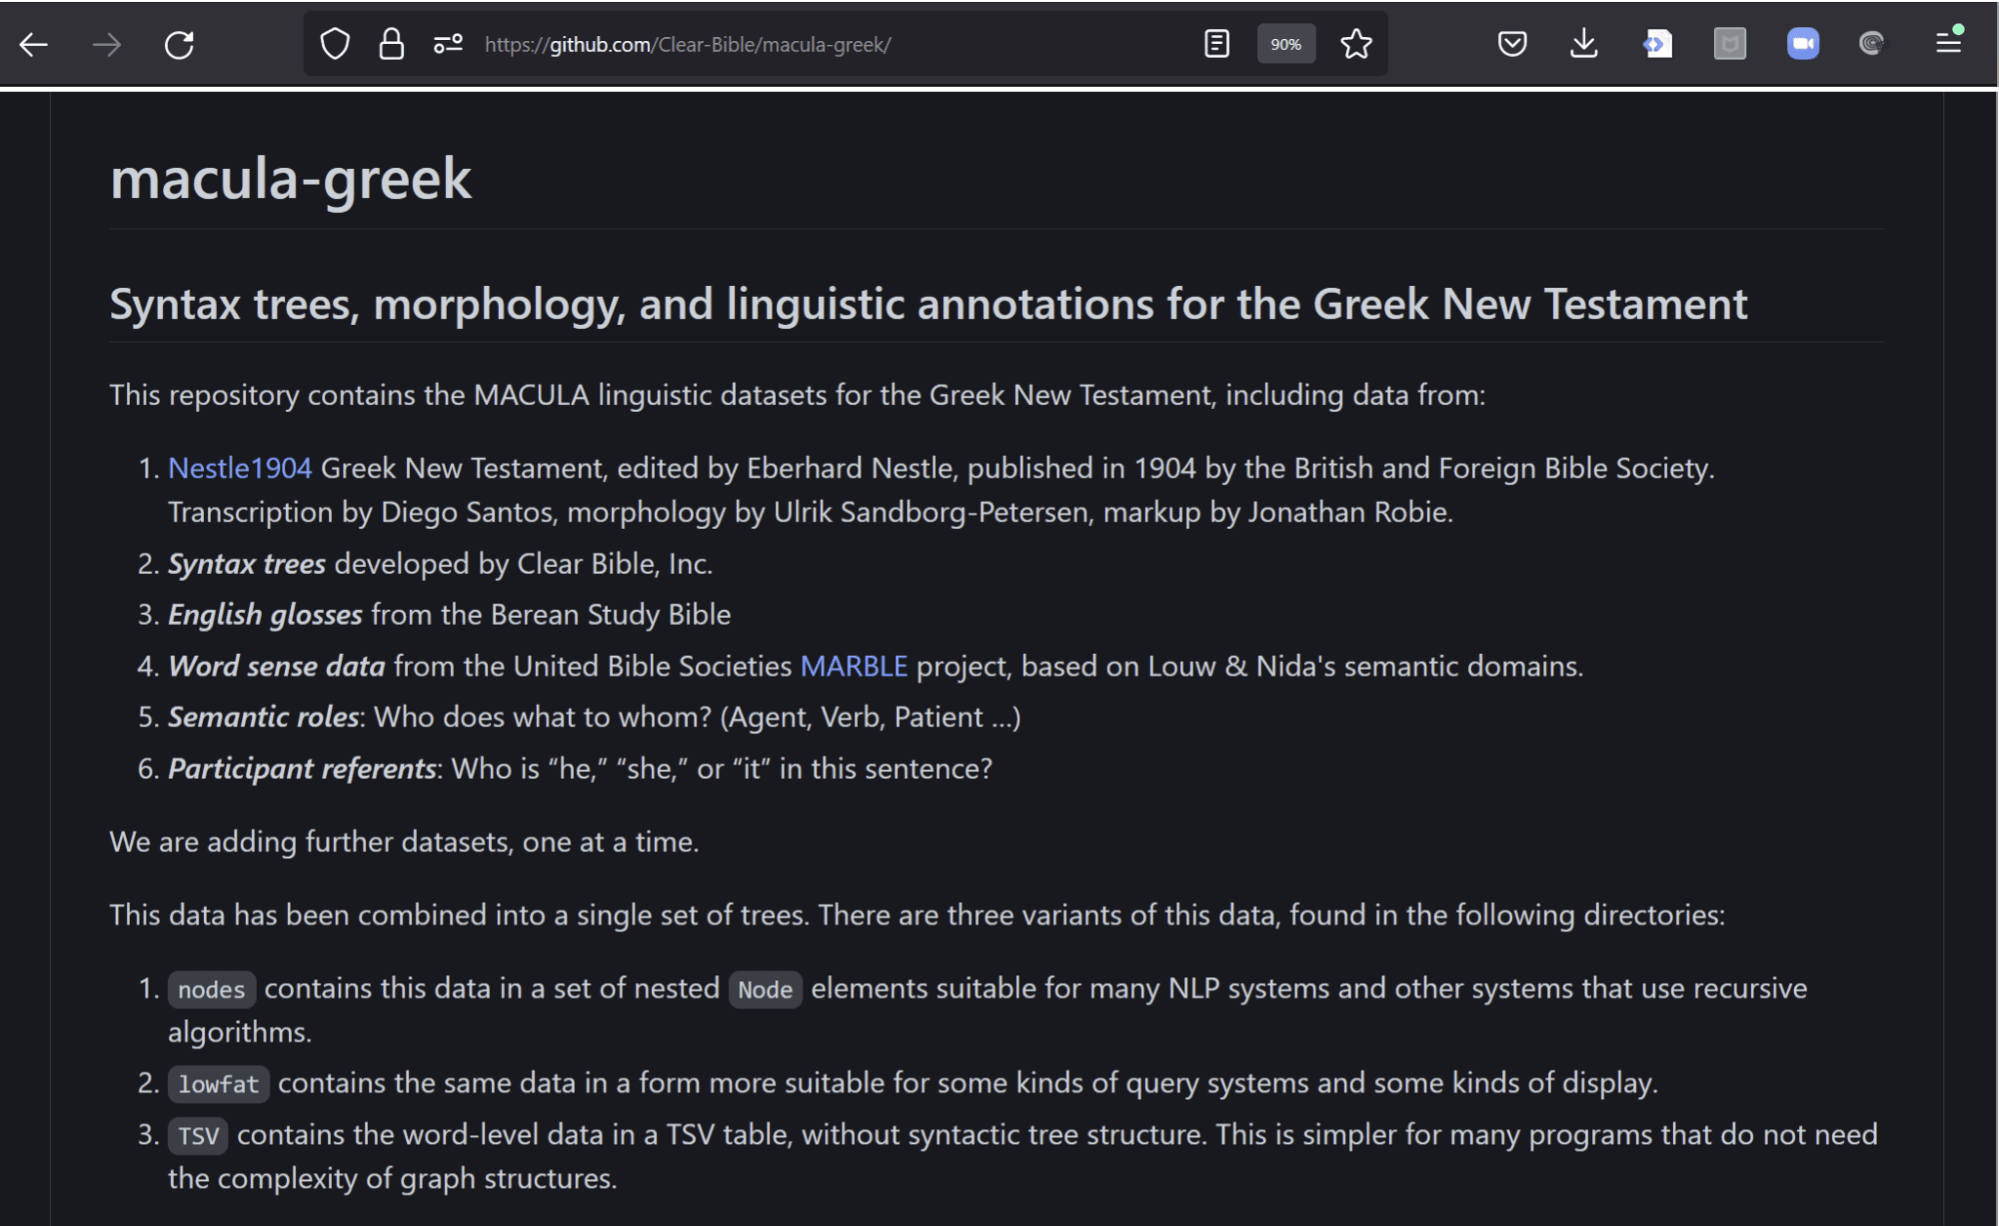
O MACULA inclui conjuntos de dados ricos (acessíveis via GitHub e por meio de uma API). Esses conjuntos de dados fornecem muitas camadas de descrição linguística para cada sentença da Bíblia Hebraica e do Novo Testamento Grego, incluindo estrutura sintática, morfologia, domínios semânticos, relacionamentos, referentes, glosas e citações, e outros aspectos.
O MACULA pode ser usado por criadores de recursos ou pesquisadores com conhecimento extensivo de línguas bíblicas e linguística, ou por programadores e profissionais de NLP que não conhecem hebraico e grego. Os conjuntos de dados do MACULA são licenciados gratuitamente e disponíveis no GitHub.
https://github.com/Clear-Bible/macula-hebrew
https://github.com/Clear-Bible/macula-greek
Usando esses conjuntos de dados como base, a Clear está em processo de criar ambientes de usuário tanto para estudiosos de línguas bíblicas quanto para estudantes sérios da Bíblia que não conhecem grego ou hebraico.
Telas
Testemunhos
"As a Data Scientist wanting to process the biblical texts, I have found the MACULA dataset to be extremely useful. The data is very high quality, and it's very straightforward for me to import and use it in developing applications!"
Mark Woodward, Data Scientist, SIL International
"The MACULA data sets help translation consultants quickly recognize features, including participant reference and word sense, of the biblical texts. We appreciate the way it already integrates UBS and other data sets and look forward to even richer data in the future."
Milt Jones, VP Bible Translation at Seed Company
"MACULA data has been a game changer for our team as we try to estimate the qualities of Bible translation drafts. The semantic domain information and glosses help us find missing, added, or modified information during review."
Daniel Whitenack, Data Scientist, SIL Internationa