MACULA
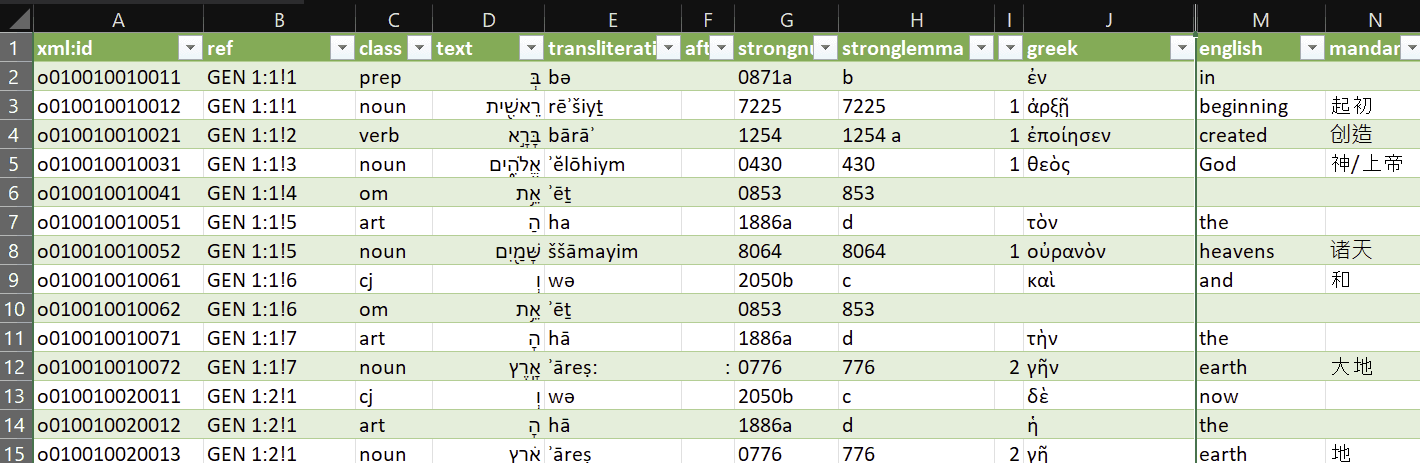
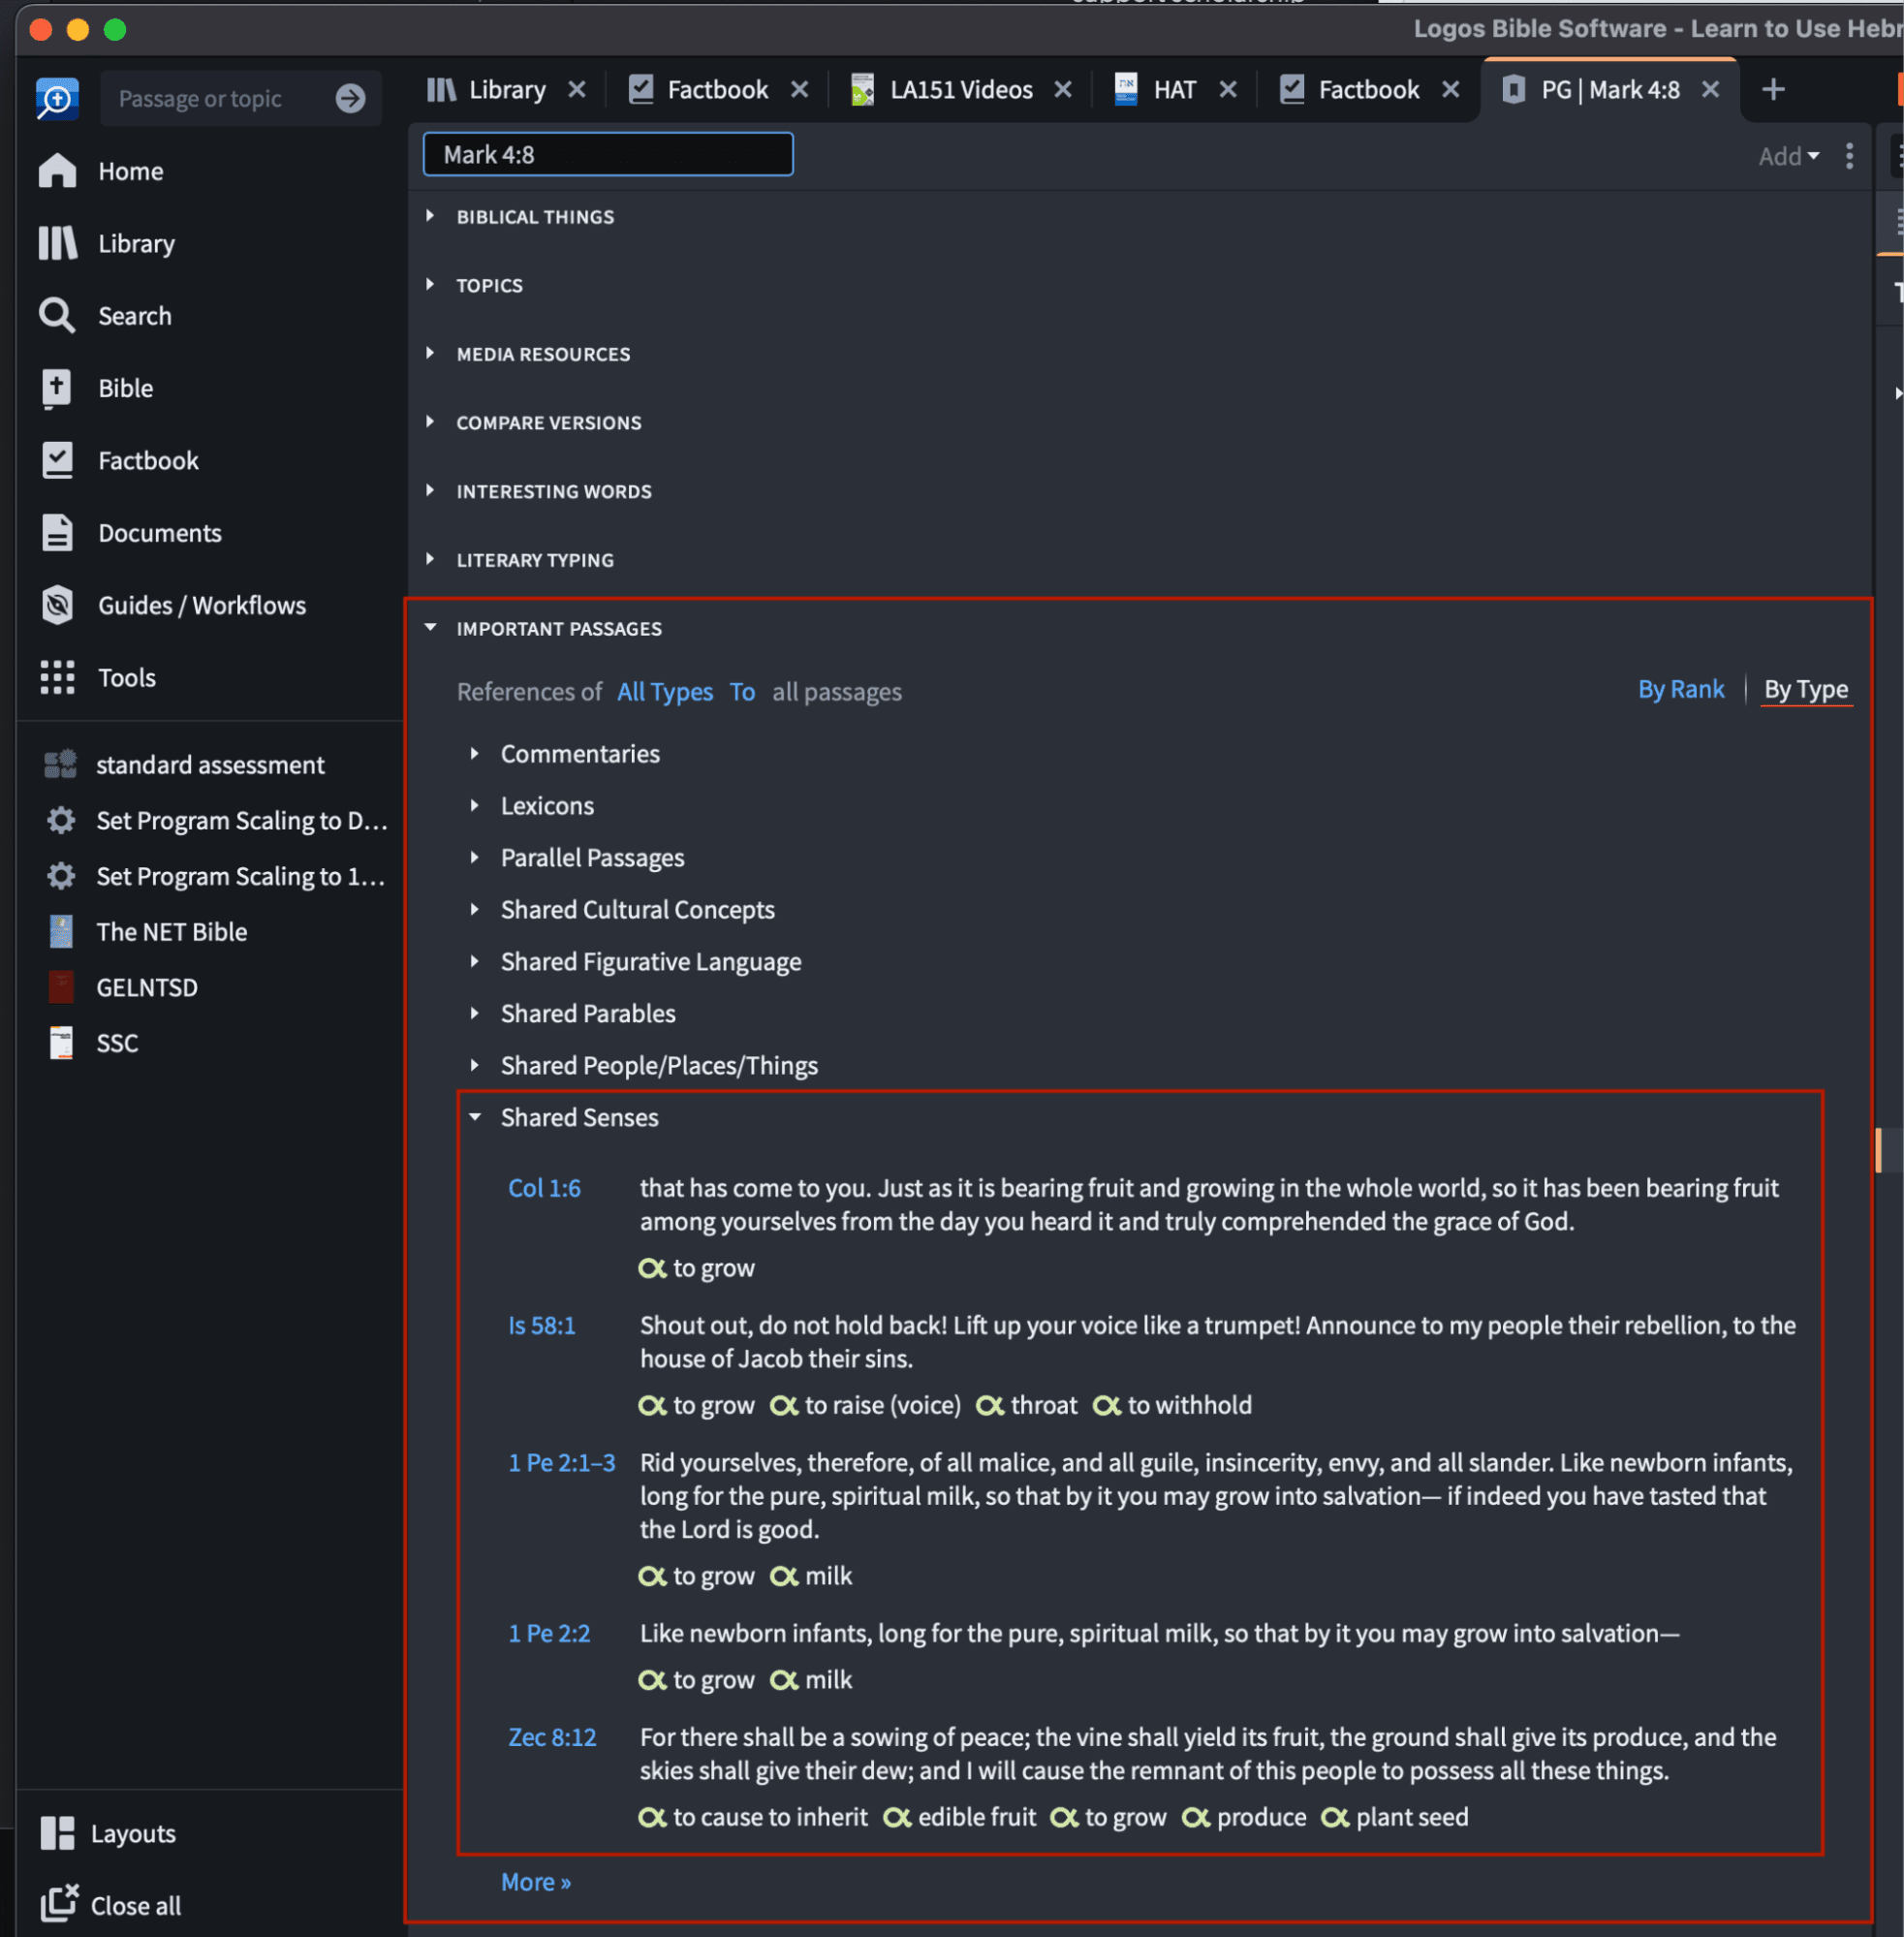
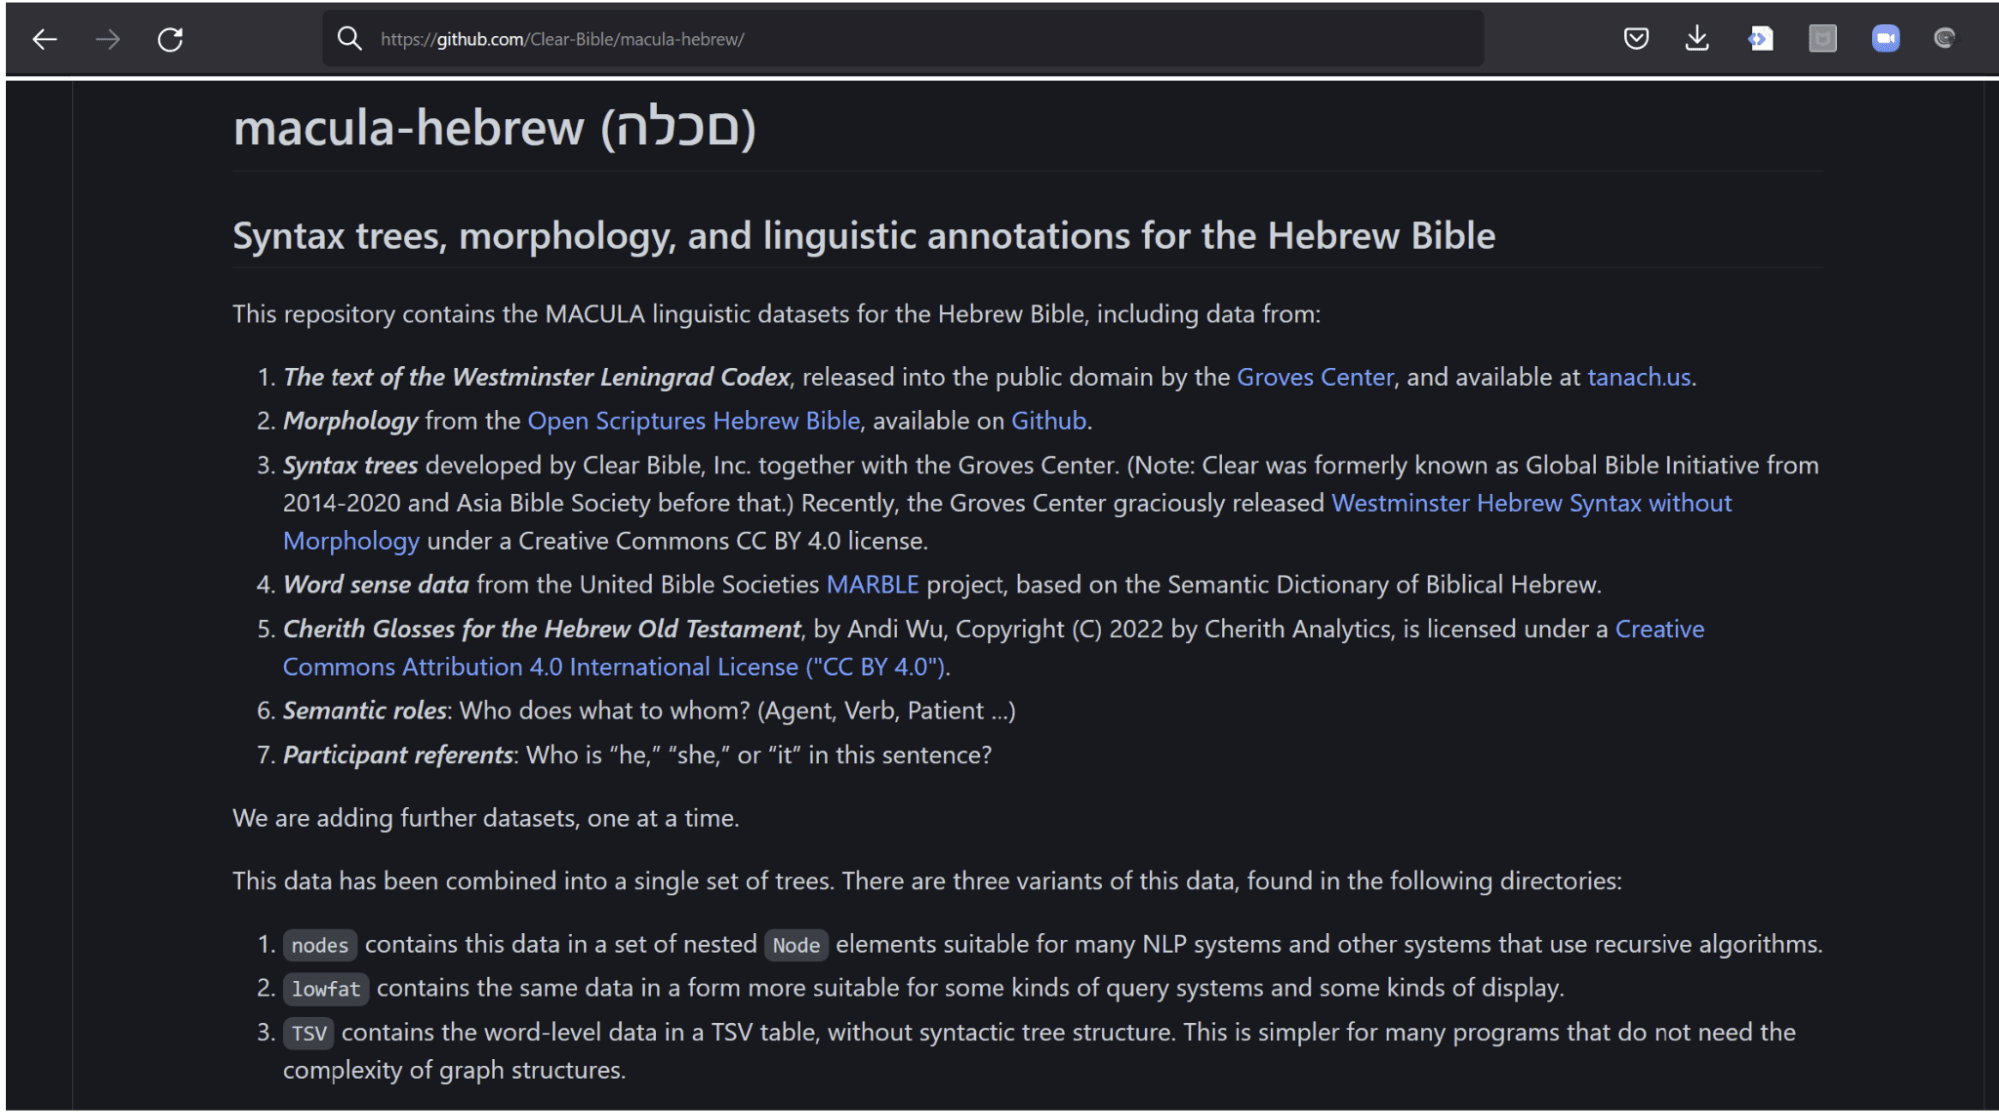
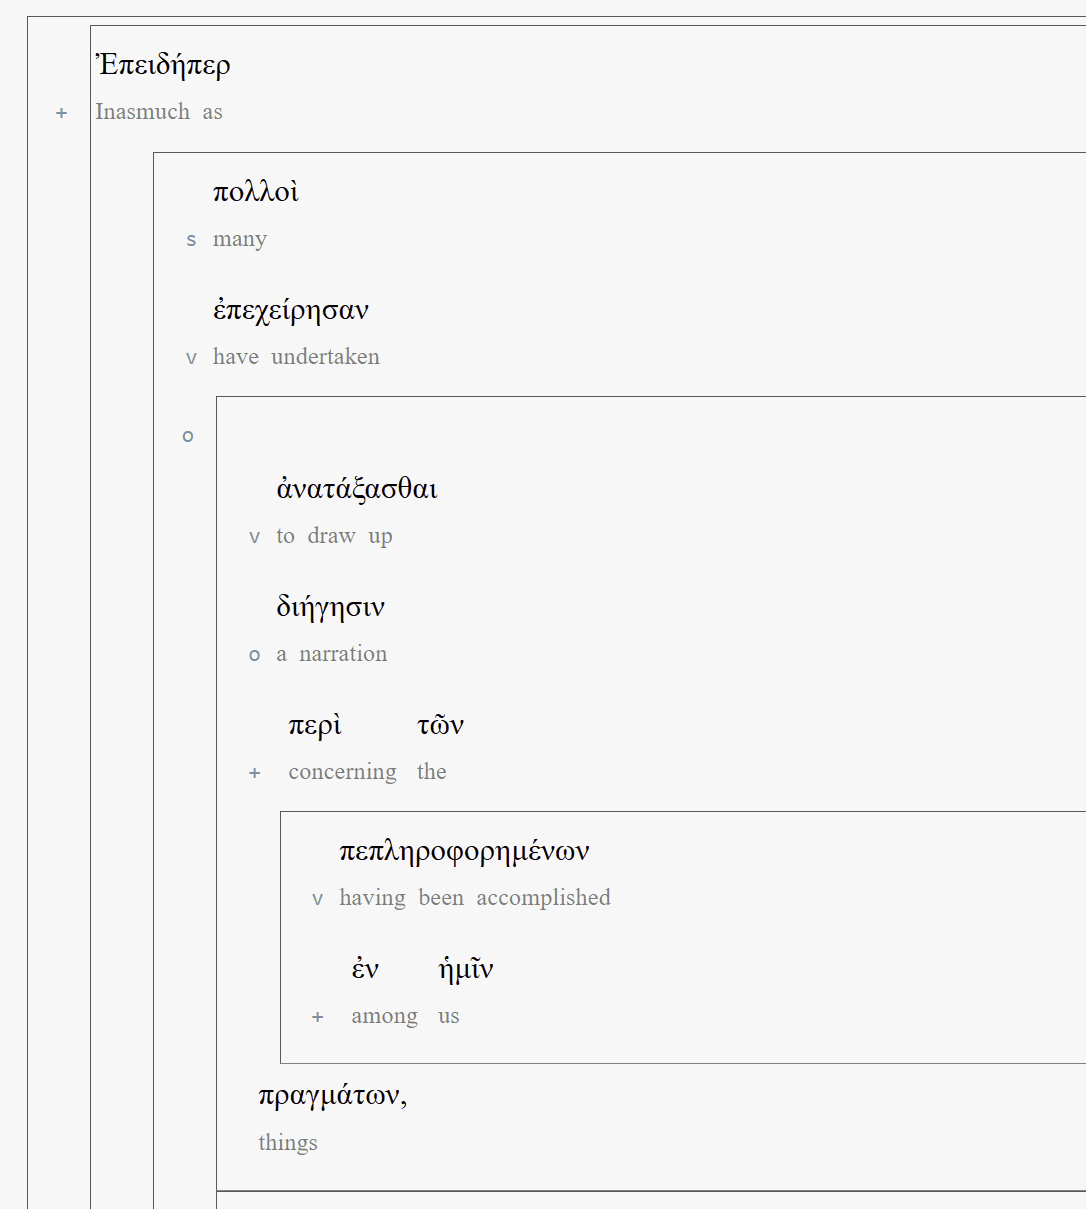
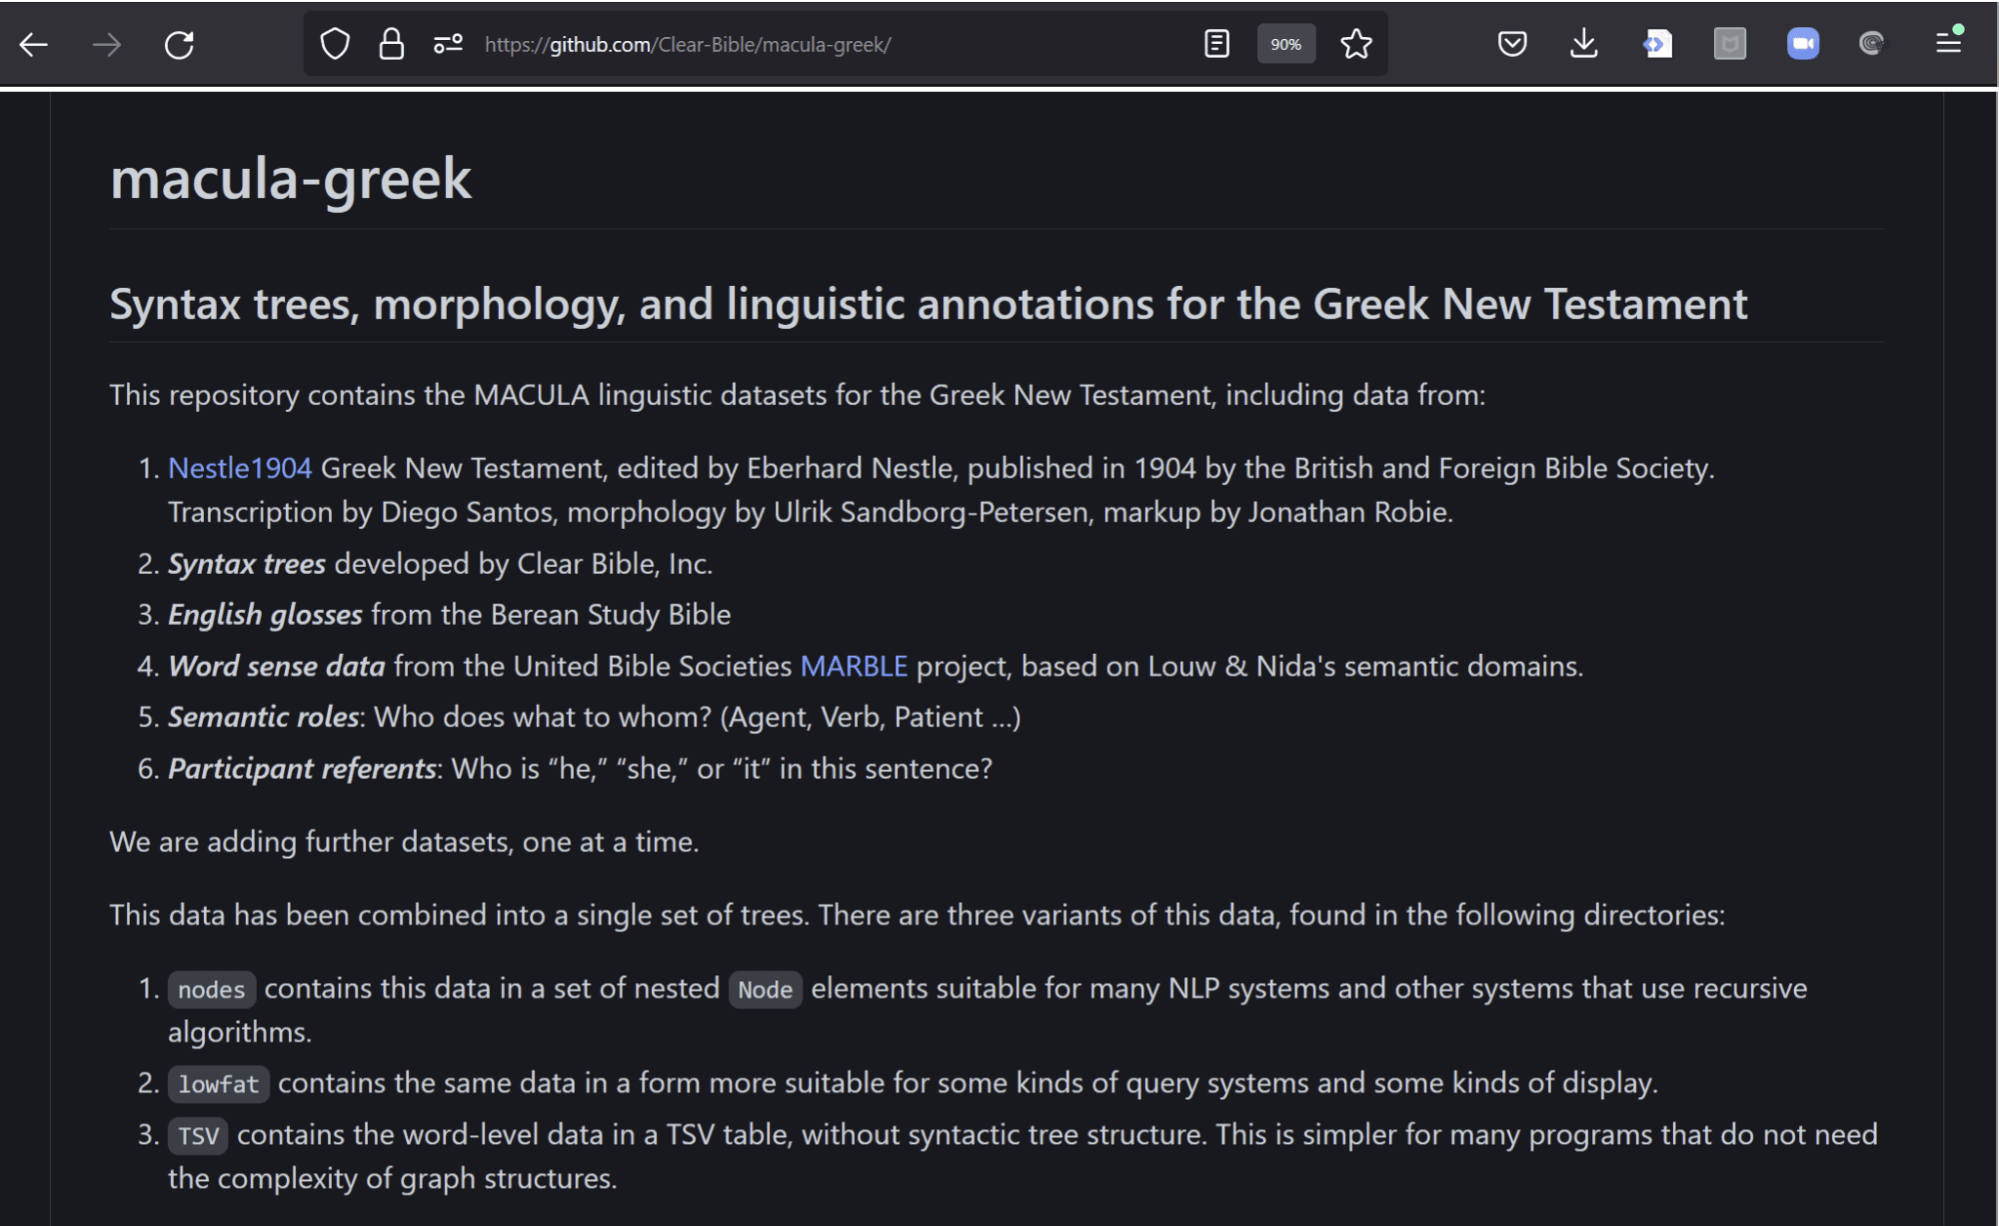
MACULA includem olsem dataset (save access via GitHub mo via API). Olem dataset ia providem olsem lewel we language description long every sentence blong Hebrew Bible mo Greek New Testament, includem sintaks structure, morphology, semantic domains, relationship, referents, glosses, mo quotations, mo narafala aspect.
MACULA hem useable blong resource creators mo researchers we got extensive knowledge blong biblical languages mo linguistics, mo blong programmers mo NLP practitioners we no save Hebrew mo Greek. MACULA dataset hem freely licensed mo available long GitHub.
https://github.com/Clear-Bible/macula-hebrew
https://github.com/Clear-Bible/macula-greek
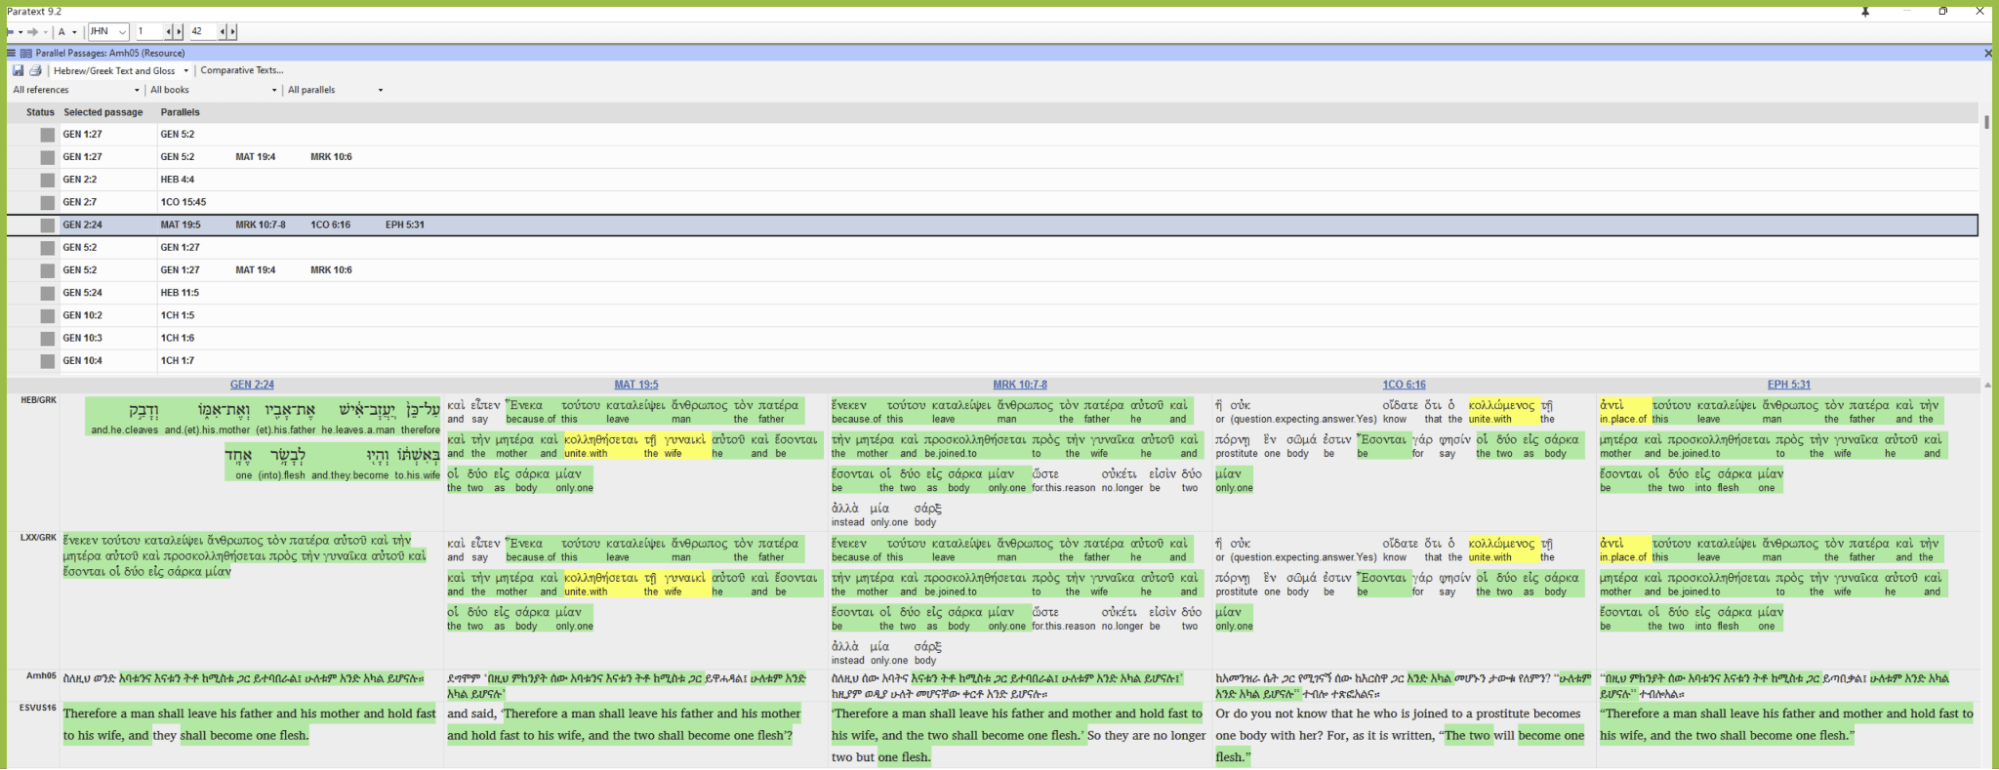
Using these datasets as a basis, Clear is in the process of creating user environments for both scholars of biblical languages and serious Bible students who do not know Greek or Hebrew.
Skrin
Testimoni
"As a Data Scientist wanting to process the biblical texts, I have found the MACULA dataset to be extremely useful. The data is very high quality, and it's very straightforward for me to import and use it in developing applications!"
Mark Woodward, Data Scientist, SIL International
"The MACULA data sets help translation consultants quickly recognize features, including participant reference and word sense, of the biblical texts. We appreciate the way it already integrates UBS and other data sets and look forward to even richer data in the future."
Milt Jones, VP Bible Translation at Seed Company
"MACULA data has been a game changer for our team as we try to estimate the qualities of Bible translation drafts. The semantic domain information and glosses help us find missing, added, or modified information during review."
Daniel Whitenack, Data Scientist, SIL Internationa