मकुला
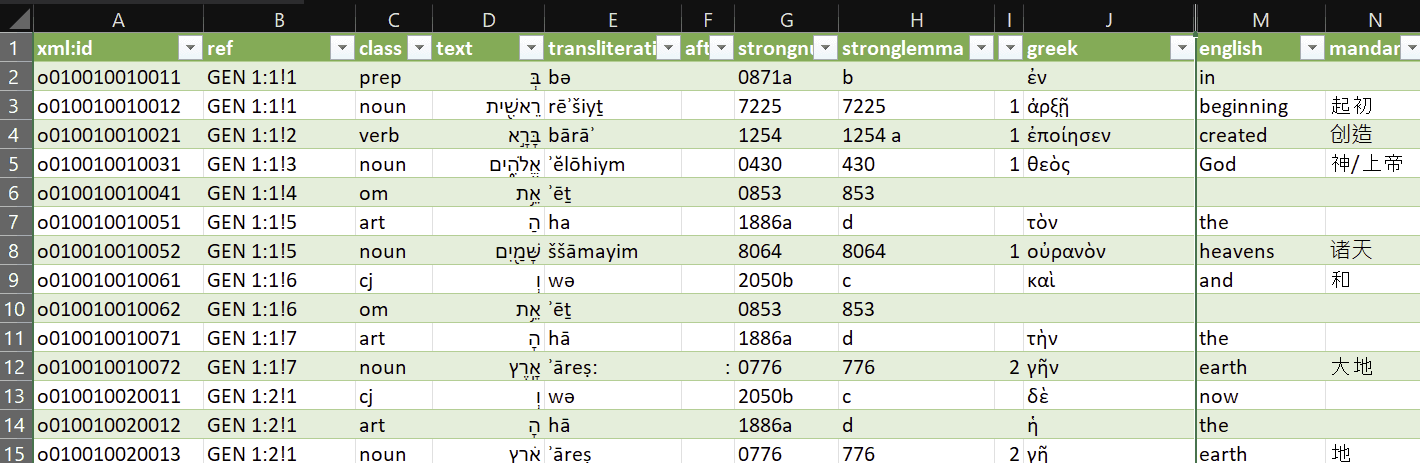
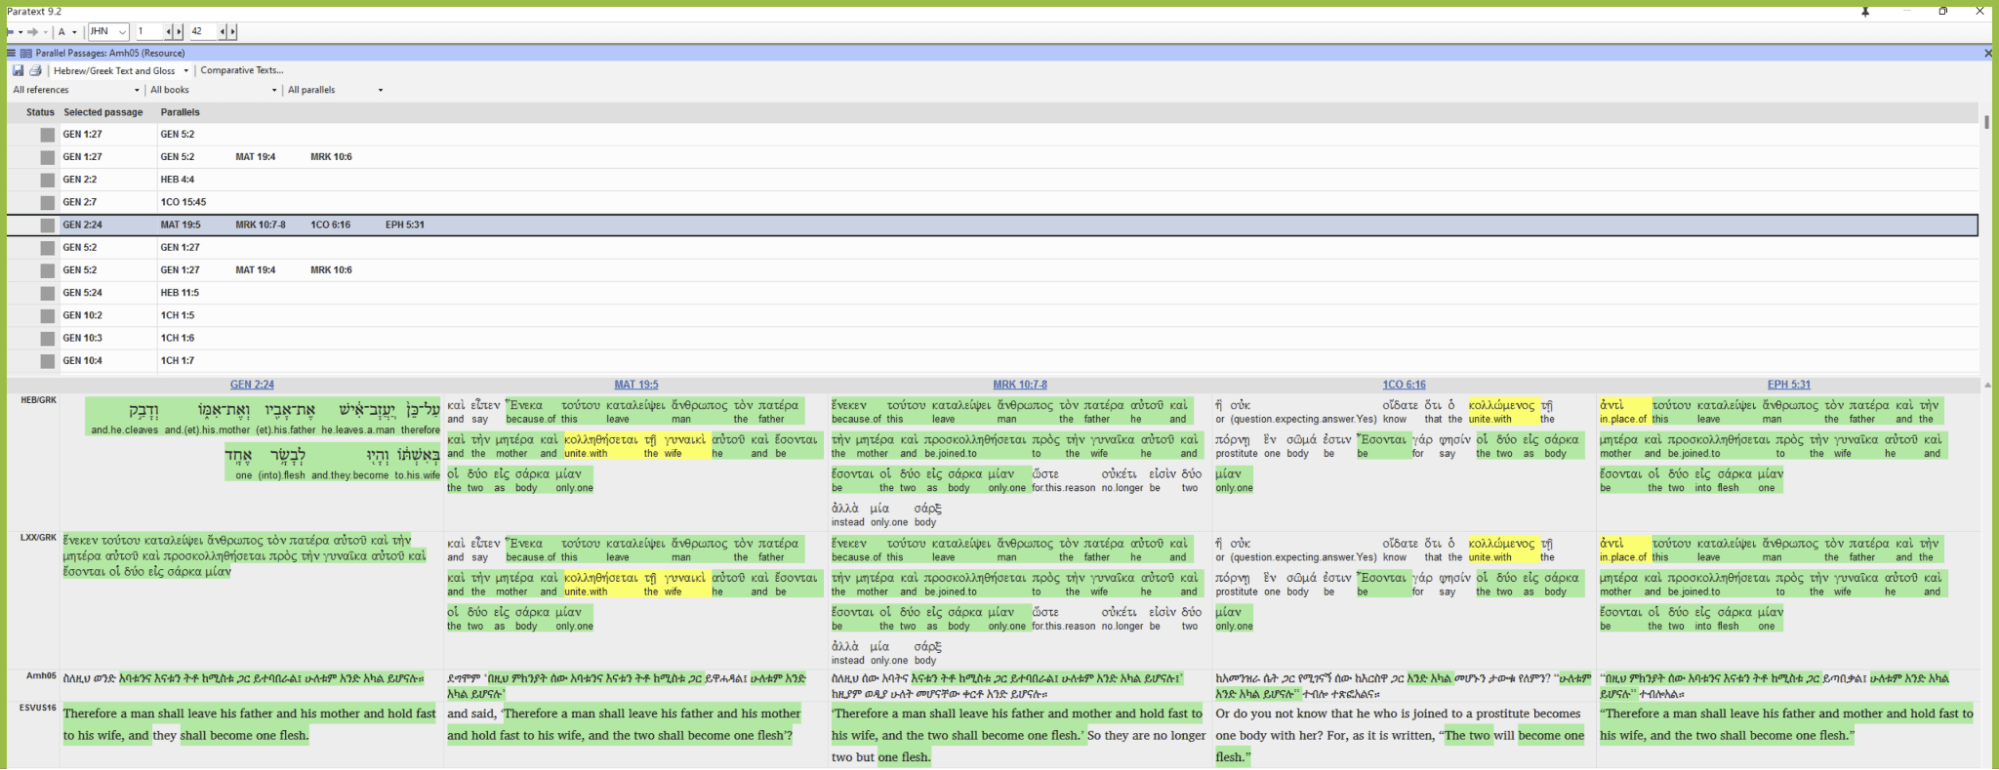
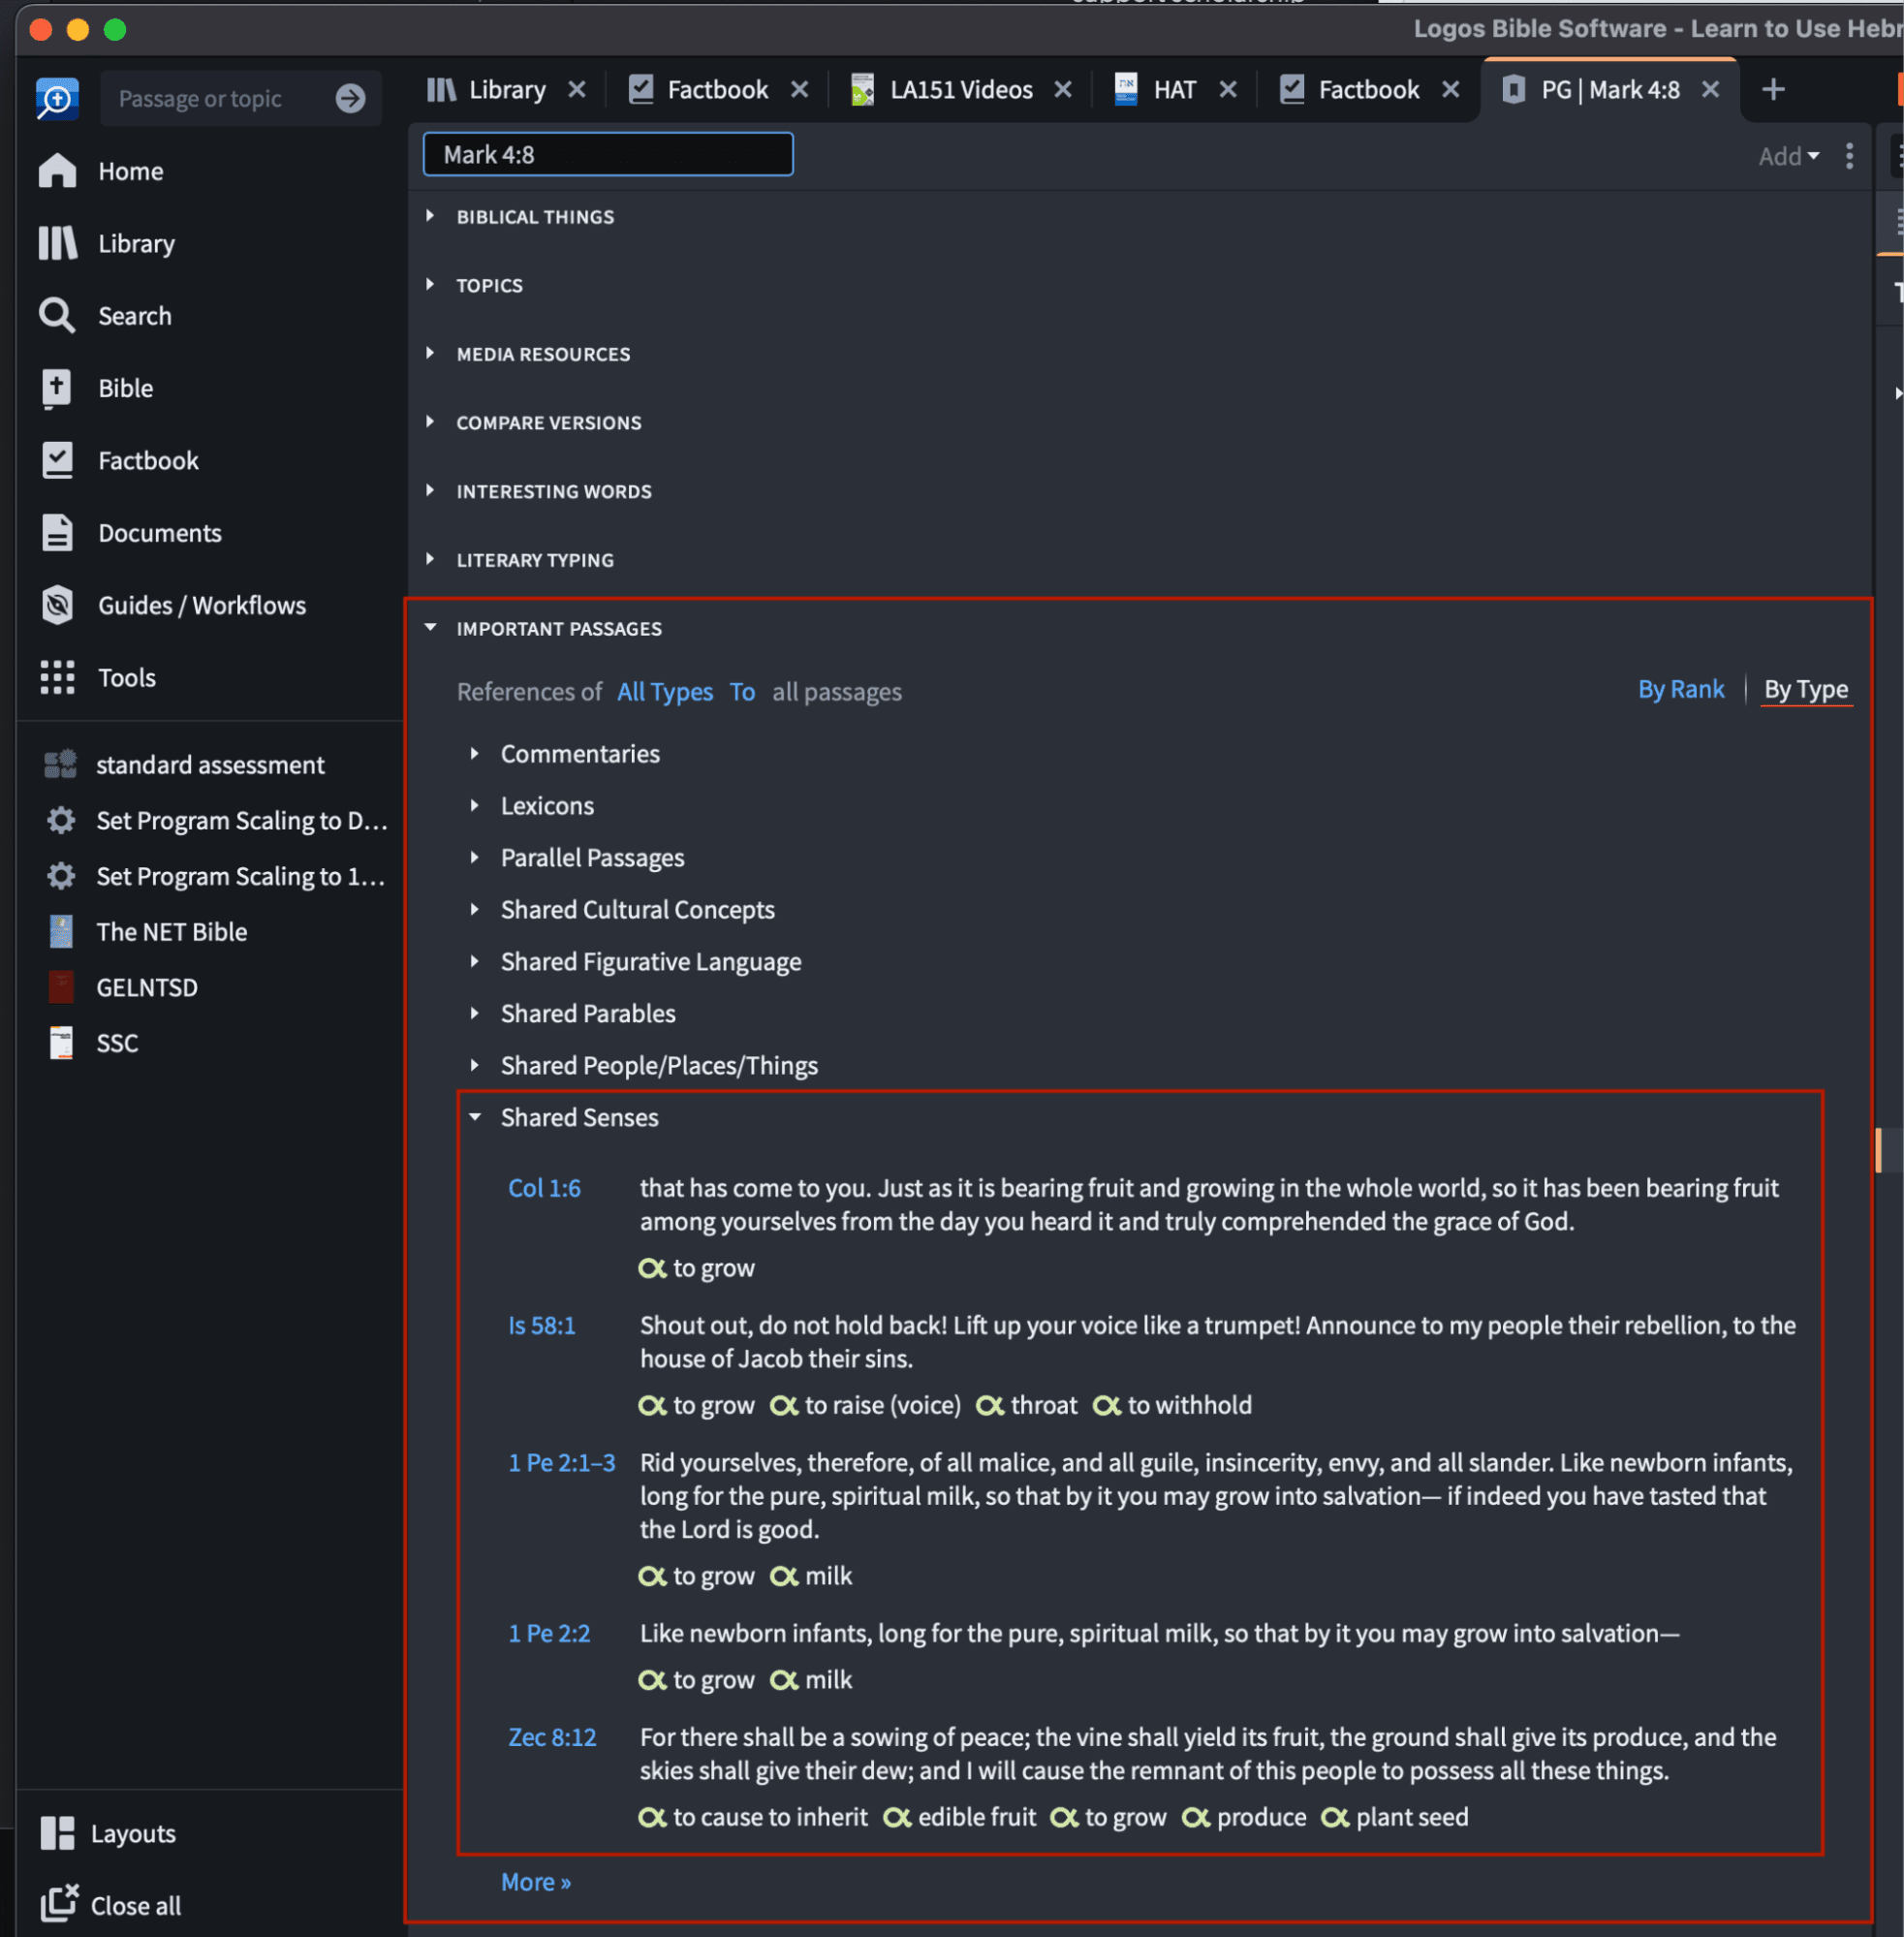
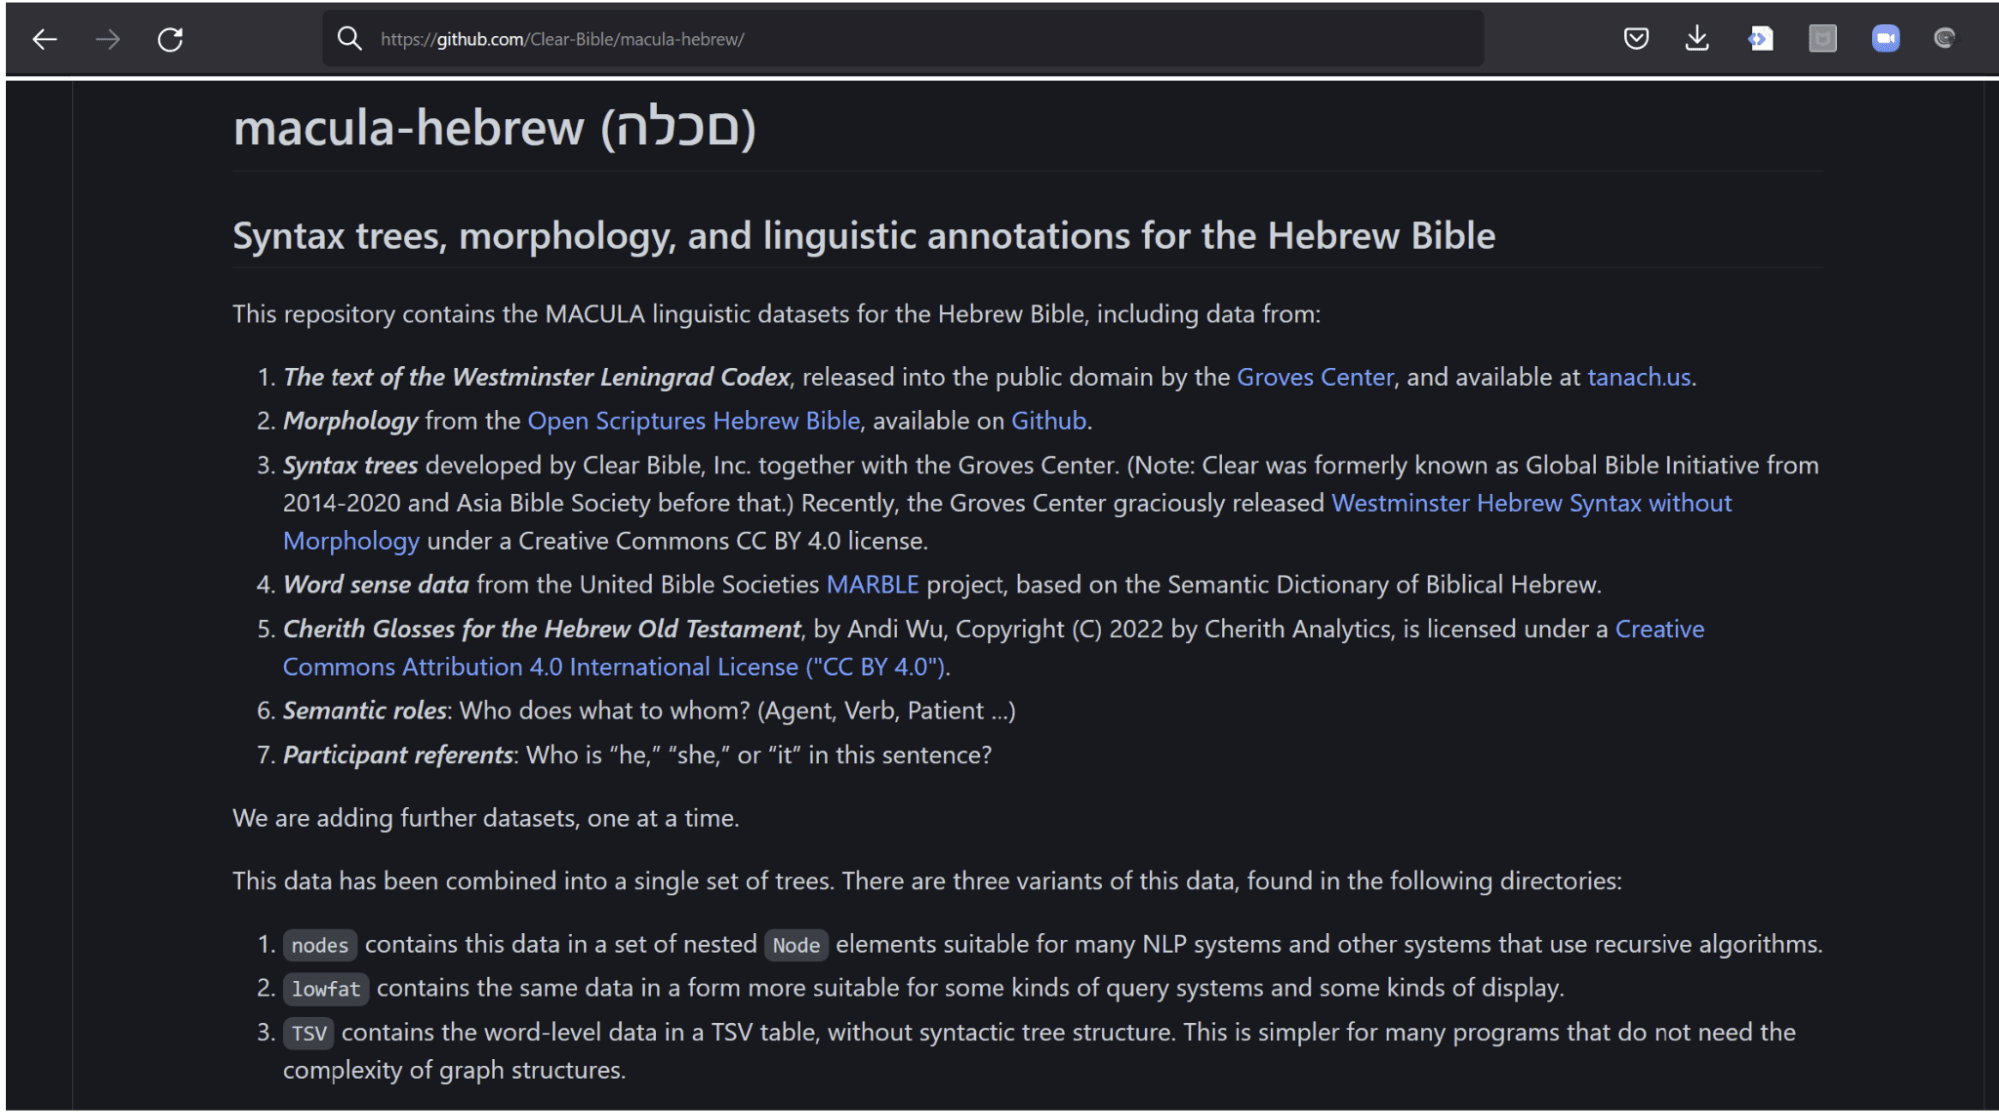
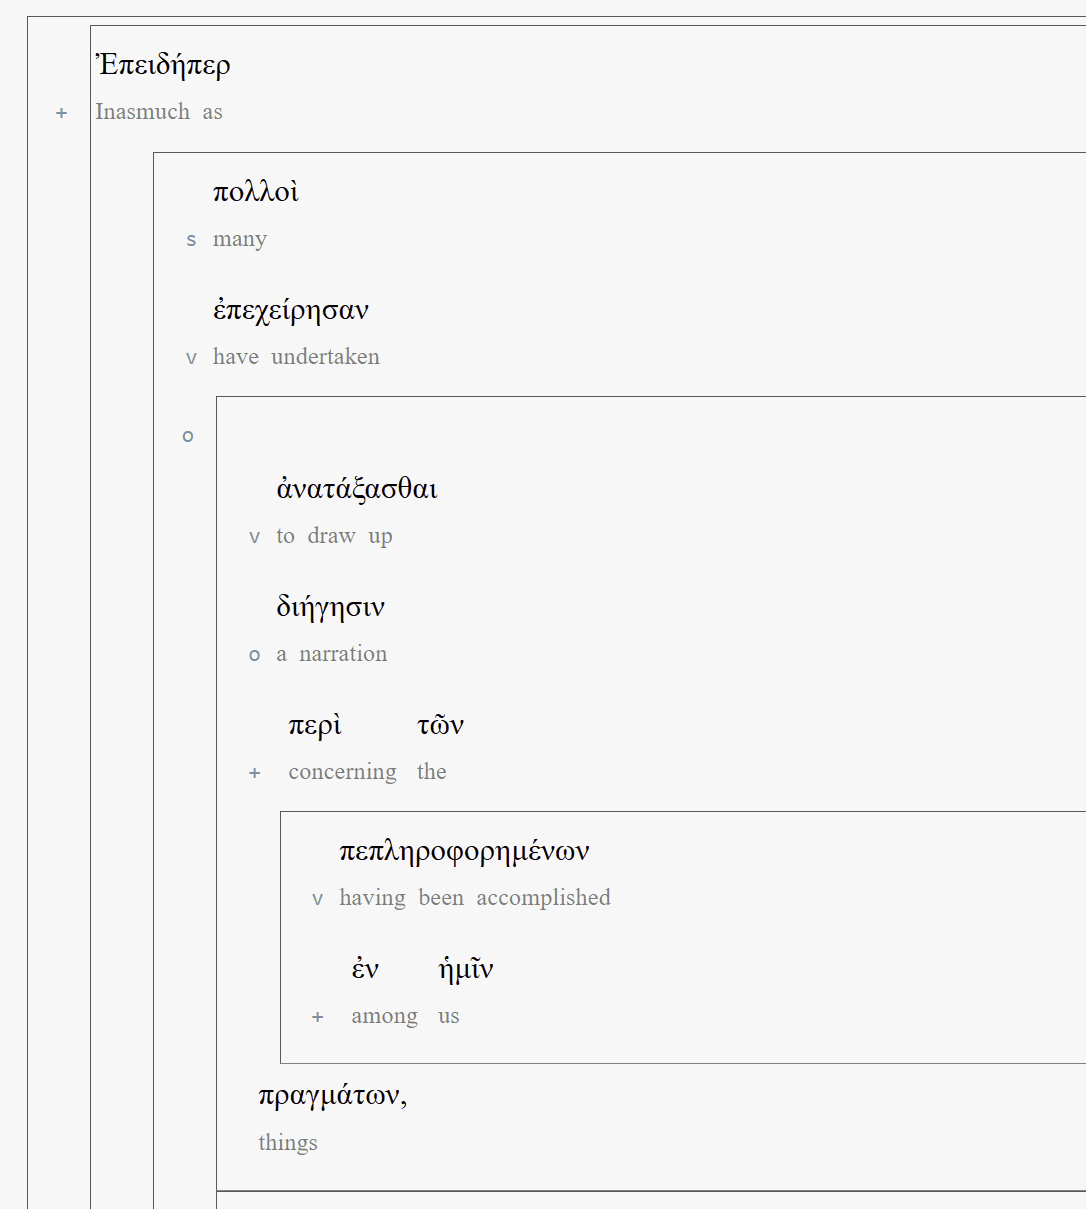
मकुला में समृद्ध डेटासेट शामिल हैं (GitHub और API के माध्यम से पहुँचा जा सकता है)। ये डेटासेट हिब्रू बाइबल और ग्रीक न्यू टेस्टामेंट की हर वाक्य के लिए कई स्तरों का भाषाई विवरण प्रदान करते हैं, जिसमें वाक्य रचना संरचना, रूपวิทยा, अर्थ 영역, संबंध, संदर्भ, ग्लosses, उद्धरण, और अन्य पहलू शामिल हैं।
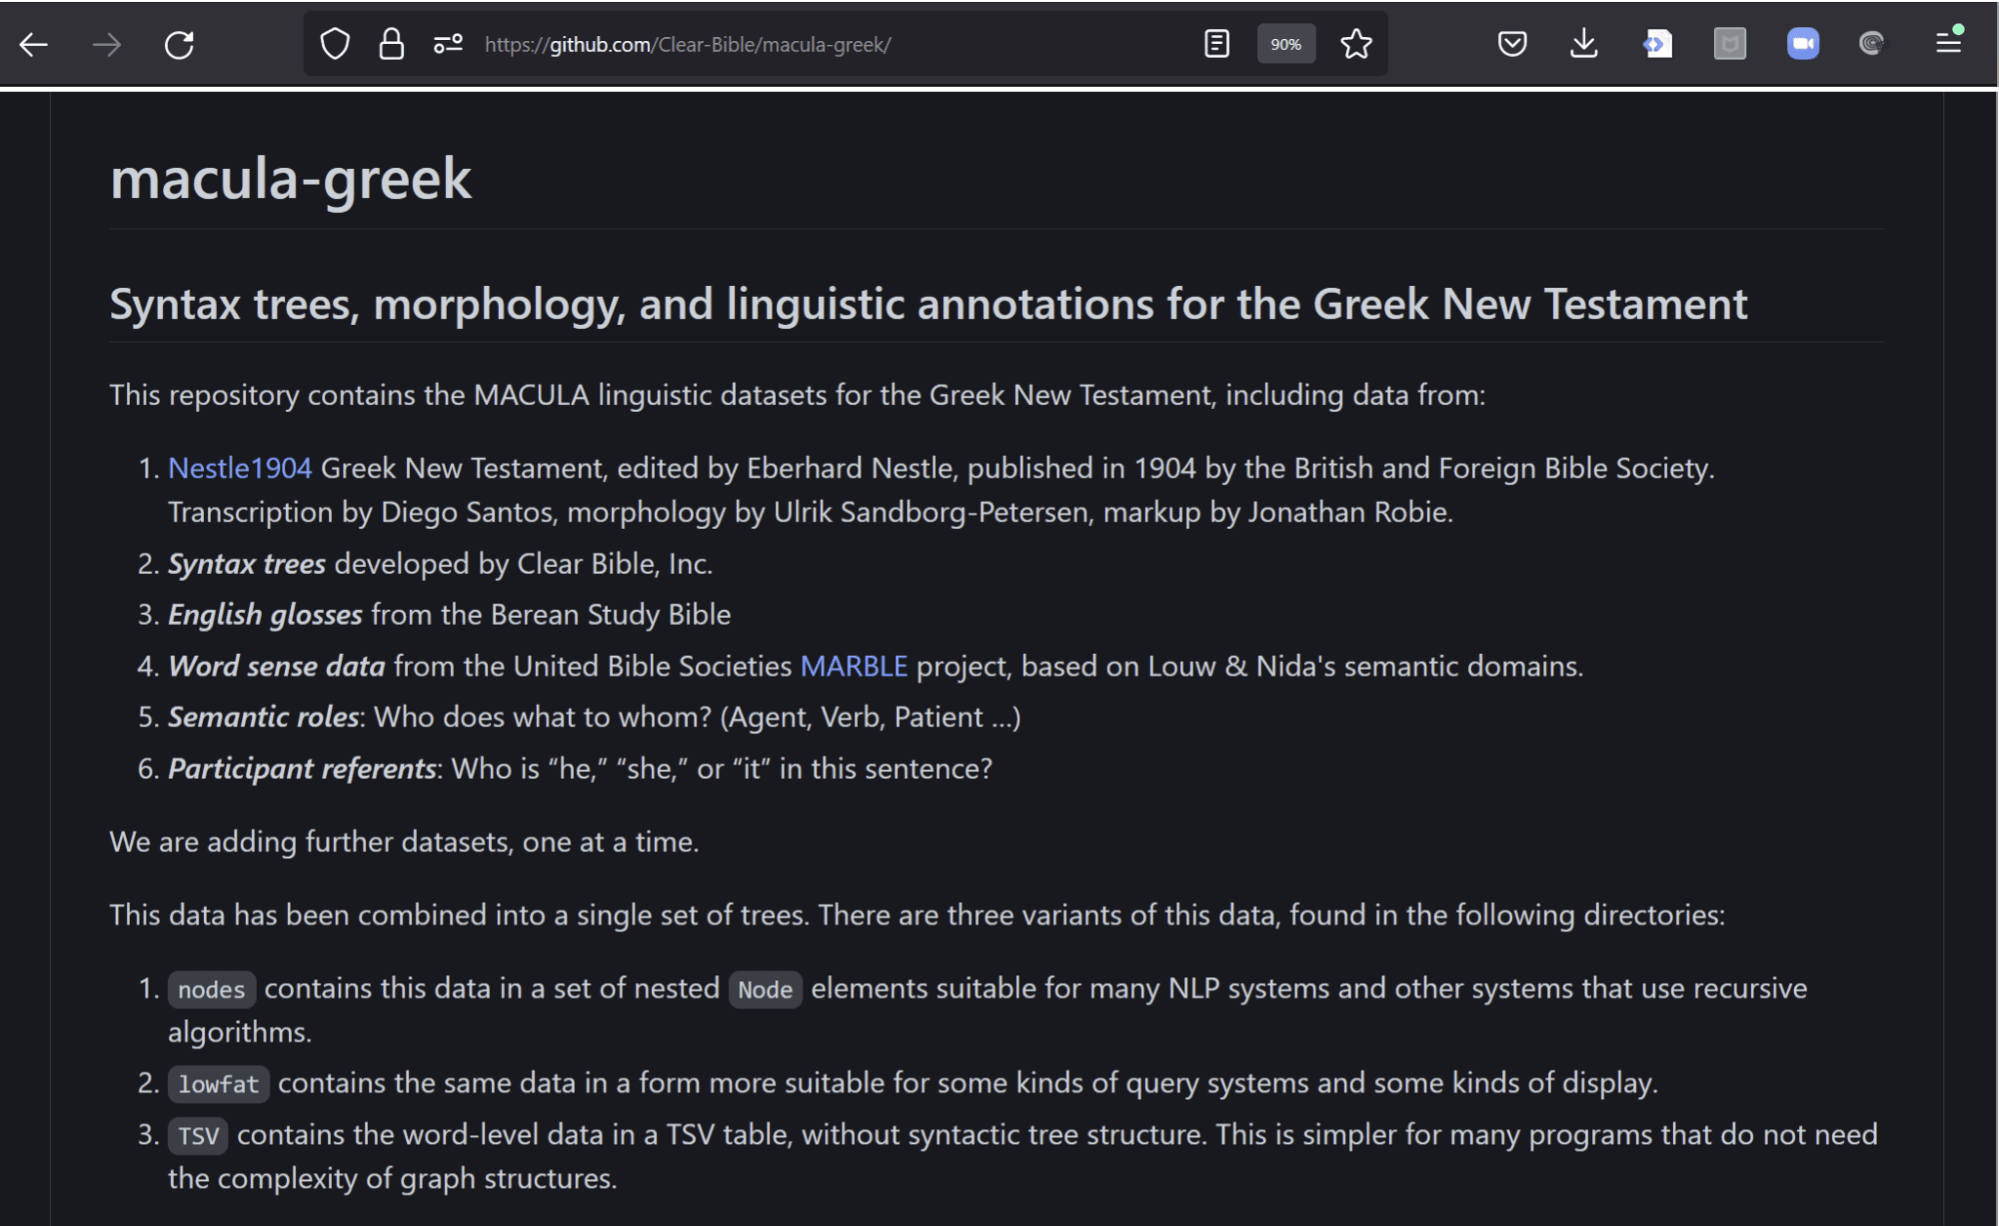
मकुला का उपयोग संसाधन निर्माताओं या शोधकर्ताओं द्वारा किया जा सकता है जिनके पास बाइबिल भाषाओं और भाषाई ज्ञान का व्यापक ज्ञान है, या प्रोग्रामर और प्राकृतिक भाषा प्रसंस्करण चिकित्सकों द्वारा जो हिब्रू और ग्रीक नहीं जानते हैं। मकुला के डेटासेट स्वतंत्र रूप से लाइसेंस प्राप्त हैं और GitHub पर उपलब्ध हैं।
https://github.com/Clear-Bible/macula-hebrew
https://github.com/Clear-Bible/macula-greek
इन डेटासेट का उपयोग करके, क्लियर बाइबल भाषाओं के विद्वानों और गंभीर बाइबल छात्रों के लिए उपयोगकर्ता वातावरण बनाने की प्रक्रिया में है, जो ग्रीक या हिब्रू नहीं जानते हैं।
स्क्रीन
प्रशंसापत्र
"As a Data Scientist wanting to process the biblical texts, I have found the MACULA dataset to be extremely useful. The data is very high quality, and it's very straightforward for me to import and use it in developing applications!"
Mark Woodward, Data Scientist, SIL International
"The MACULA data sets help translation consultants quickly recognize features, including participant reference and word sense, of the biblical texts. We appreciate the way it already integrates UBS and other data sets and look forward to even richer data in the future."
Milt Jones, VP Bible Translation at Seed Company
"MACULA data has been a game changer for our team as we try to estimate the qualities of Bible translation drafts. The semantic domain information and glosses help us find missing, added, or modified information during review."
Daniel Whitenack, Data Scientist, SIL Internationa